Enterprise AI Agents: From Chatbots to Autonomous Workflows
Updated and source-checked:
Editorial note: Some links in this article are affiliate links — we may earn a commission if you sign up, at no extra cost to you. Research guides are distinguished from documented firsthand reviews in our editorial standards. Read our editorial standards →
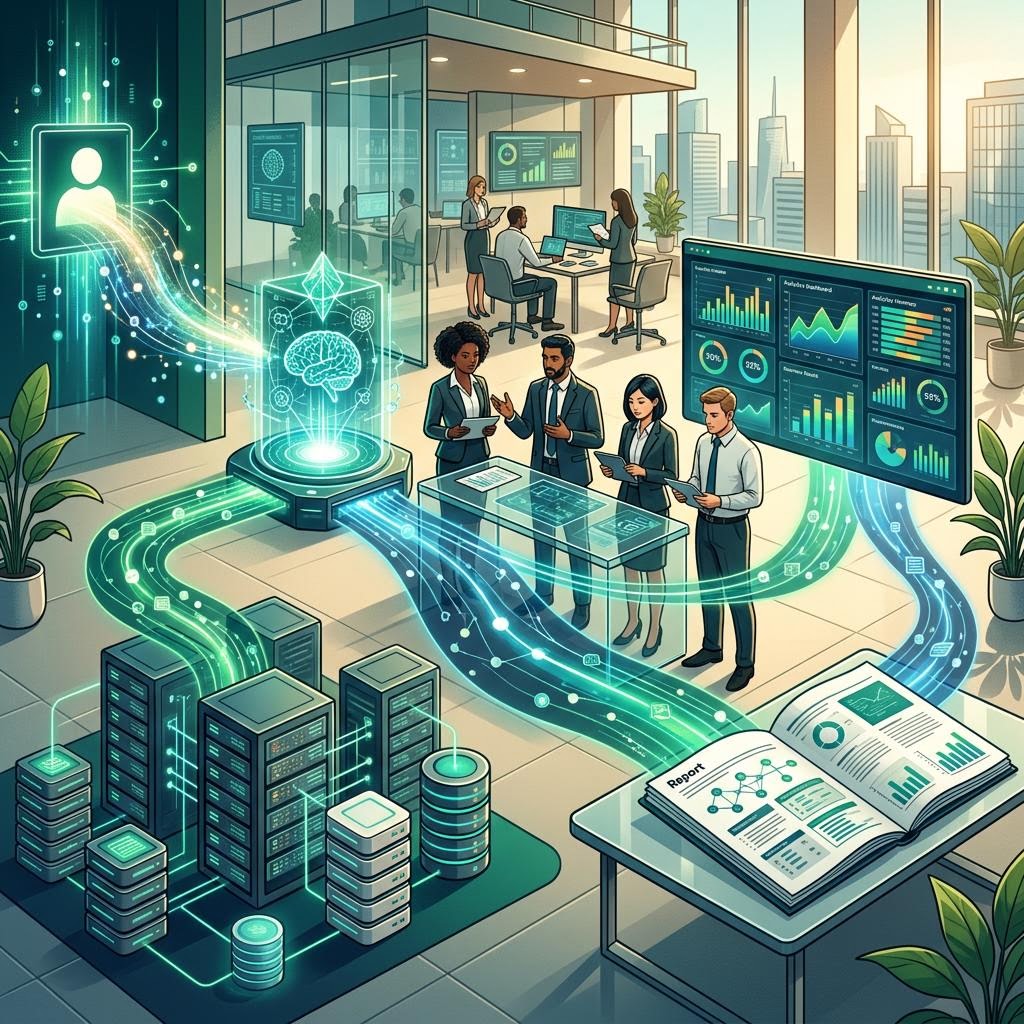
A customer asks for a quarterly usage review. A chatbot can draft a reply, but someone still has to find the account, query usage, check support history, assemble the evidence and send the report. An enterprise AI workflow connects those steps and keeps track of what happened between them.
That is the useful promise of enterprise AI agents in 2026: delegating a defined piece of work across approved systems. The hard part is deciding which steps the model may choose, which rules the software must enforce and where a person accepts responsibility for the result.
This guide explains how to make those decisions. It includes an illustrative account-review workflow, a practical architecture and a 30-day pilot plan. The examples are design proposals, not results from a production deployment or a vendor benchmark.
Original illustration created for Teach AI Tools.
Chatbots, workflows and agents: what actually changes?
A chatbot is an interface. It can sit in front of a simple question-answering system or a sophisticated agent. The architecture underneath determines whether it can carry work forward.
Anthropic’s engineering guide distinguishes predefined workflows from agents that dynamically select their own steps and tools. That distinction is useful when planning a project: a process with several AI calls does not automatically need an autonomous planner. The guide was originally published in December 2024; we use its architectural distinction here, rather than its older tooling examples.
| Approach | How the next step is chosen | Example | Main tradeoff |
|---|---|---|---|
| Chat assistant | A person directs each request | Summarize a supplied account report | The person coordinates the remaining work |
| Rules-based automation | Code follows fixed conditions | Create a task when a form arrives | Brittle when inputs or exceptions vary |
| AI workflow | Code controls the sequence; AI interprets selected inputs | Classify a support ticket, retrieve context and draft a reply | Needs reliable routing and output checks |
| Bounded agent | A model chooses among approved actions within enforced limits | Investigate a usage anomaly and request relevant evidence | More variable cost, latency and failure paths |
Use a fixed workflow when you already know the sequence. Add agentic choices where the next useful step depends on evidence found during the task. In either case, keep business permissions outside the prompt so the application can enforce them.
What the 2026 announcements tell us
In its April 22, 2026 Gemini Enterprise announcement, Google described multi-step agents running over hours or days, alongside identity, registry and gateway controls. This shows the product direction toward persistent execution and oversight. A product announcement alone does not establish reliability, savings or suitability for your workflow.
Gartner’s August 26, 2025 forecast projected that 40% of enterprise applications would integrate task-specific AI agents by the end of 2026, compared with less than 5% at the time. It is a forecast about application features, not a measured adoption result, a productivity statistic or a claim that 40% of work will be autonomous.
For a buyer, the useful question is whether a product can complete your defined task with acceptable evidence, cost and oversight. Ask the vendor to demonstrate an expired credential, missing data and a rejected approval as well as the successful path.
Choose a workflow with a clear finish line
Start with a task that repeats, has an accountable owner and produces an output people can check. Support handoffs, account-review drafts and data-quality investigation packets are reasonable candidates when their data access is already understood.
Write the acceptance criteria before selecting a platform. For an account review, these might require the correct customer and reporting period, reconciled totals, links to supporting records and an explicit list of missing evidence. “Create an insightful report” gives a reviewer too little to assess.
- Frequency: Does the task happen often enough to justify integration and maintenance?
- Data readiness: Are identifiers, definitions and access rules consistent across the source systems?
- Reviewability: Can the owner verify the important claims without repeating every step?
- Recoverability: Can a failed run stop safely and leave the task available for manual completion?
If most of the work is a stable sequence of database lookups and templates, conventional automation may be sufficient. If the proposed workflow needs unrestricted access to make progress, narrow the task before adding intelligence.
Source photo: Pexels, used under the Pexels License.
Worked example: prepare a quarterly account review
Illustrative design: a customer-success team wants a draft report for one account and one completed quarter. The agent may read approved records and save a draft in an internal review queue. The account owner approves and sends the final report.
| Step | Allowed operation | Check or stopping condition |
|---|---|---|
| 1. Validate the request | Resolve the account and reporting dates using authorized CRM records | Ask for clarification if more than one account matches |
| 2. Collect evidence | Call a parameterized usage query and retrieve permitted support records | Return a missing-data status if a required source is unavailable |
| 3. Calculate changes | Use deterministic code for totals and quarter-on-quarter comparisons | Reconcile periods and units; do not invent a percentage when the prior value is zero |
| 4. Investigate exceptions | Choose among approved lookups for unexplained changes | Stop at the configured tool-call, time or spend limit |
| 5. Draft the report | Generate a summary with source references and unresolved questions | Separate observed facts from possible explanations |
| 6. Request review | Save a versioned draft and notify the internal review queue | Require the owner to approve the exact draft before any sending action |
Suppose usage falls while support tickets rise. The model can identify the overlap and retrieve the relevant incidents. It should describe a possible relationship unless the evidence establishes causation. A plausible explanation is not enough to state that an outage caused the decline.
The handoff should include the request ID, account ID, reporting window, source timestamps, calculation outputs, draft version, unresolved questions and reviewer status. A polished summary without that context is harder to trust and more expensive to correct.
Architecture: the model is one component
A useful starting structure is: request → authorization → task state → approved tools → validation → review queue → recorded outcome. Put a named business owner and an operational owner around the whole flow.
- Authorization: validate the requester and scope access to the intended account, tenant and data fields. Enforce these boundaries in the service or tool layer.
- Task state: persist progress, source versions and status. Use explicit states such as collecting, awaiting review, completed and failed so a restart does not silently repeat completed actions.
- Tool contracts: define allowed inputs and outputs. Prefer a narrow account-usage lookup to unrestricted SQL or a generic browser with broad credentials.
- Validation: check identifiers, dates, required fields and calculations before accepting generated prose.
- Action controls: bind approval to the exact action, recipient and content. A material edit after approval should trigger another review.
- Operations: record tool attempts, errors, approvals and outcome status. Apply redaction, access restrictions and retention limits to traces because they may contain sensitive data.
For an existing data platform, start from its governed views, service identities and monitoring. A new agent should consume those controls through well-defined interfaces. It should not become a shortcut around data ownership or permissions.
Design the failure paths before enabling actions
Read-only prototypes can tolerate failures that become serious once the system writes records. A timeout after a successful write, for example, can leave the caller unsure whether retrying will create a duplicate.
| Failure | Expected behavior |
|---|---|
| A connector times out | Retry only safe operations within a fixed limit, then report an incomplete task |
| A write returns an uncertain result | Check the operation ID or destination state before retrying; use idempotency where supported |
| Two systems disagree | Show the conflicting evidence and route it to the owner |
| A retrieved document tells the agent to ignore instructions | Treat retrieved text as untrusted evidence; enforce tool permissions independently of its content |
| A reviewer rejects the draft | Keep the rejection and reasons; do not treat silence or elapsed time as approval |
| A credential expires or a budget is exhausted | Stop with a visible status and a manual handoff |
Test the stop mechanism too. An operator should be able to pause new runs and prevent additional actions from active tasks. Define who handles work already in progress and how partially completed tasks are reconciled.
A practical 30-day pilot
The schedule below is a proposed starting point, not an assurance that a production deployment takes a month. Existing integrations and data quality will determine the effort.
- Days 1–7: define the baseline. Map the manual process, assign owners and collect authorized representative cases. Record completion time, review effort, error types and actual task volume. Include incomplete and ambiguous requests.
- Days 8–14: run in shadow mode. Generate drafts without customer-facing actions. Compare them with the accepted outcome and have a domain expert label unsupported claims, missing evidence and correction effort.
- Days 15–21: test exceptions. Exercise unavailable sources, access denials, duplicate events, malicious instructions in retrieved text and reviewer rejection. Check that each run reaches an understandable status.
- Days 22–30: review the decision. Compare the full workflow with the baseline. If the agreed quality and control criteria hold, consider one reversible internal action. Otherwise, fix the largest failure source or stop the pilot.
Keep a held-out set of cases that was not used to tune prompts. Re-run it when the model, prompt, connector or source schema changes. Inspect failures by type; an acceptable average can conceal repeated mistakes for a particular account or request category.
Measure completed work, including human review
Track accepted completions, elapsed time, reviewer minutes, material corrections, escalations, failed runs and total operating cost. Count an accurate escalation separately from an accepted completion: stopping safely can be correct behavior without completing the task.
Cost per accepted completion = all run costs, including failed attempts, plus allocated review and operating costs, divided by accepted completions. Track setup and integration cost separately when calculating payback.
For illustration, if a batch costs $300 in runtime and services and $200 in review and operations, with 80 accepted completions, the cost is $500 ÷ 80 = $6.25 per accepted completion. These are invented planning figures, not observed product results. Compare that cost with the manual baseline and the value of the resulting service level.
Agree on release criteria before the pilot. A team might require every material numerical claim to trace to a calculation and every external action to carry an approval record. Choose quality thresholds and sample sizes for the consequences of your task; there is no universal accuracy percentage that makes an agent ready.
When to expand autonomy
Expand one boundary at a time: an additional source, a new action or a broader account group. Recheck the relevant cases after each change. Keep a manual path available and assign ownership for connector maintenance, model changes and incidents.
The first useful milestone is a complete, evidence-backed task that its owner can review efficiently. Greater autonomy becomes justified when the workflow repeatedly meets its acceptance criteria and the team can explain, interrupt and recover its actions.
For related reading, see our AI agents and automated workflows guide and enterprise AI governance guide.
Sources and review scope
Source-checked November 12, 2026. This is an editorial research guide. The architecture, pilot schedule, failure responses and cost example are proposed implementation guidance; no enterprise deployment or commercial platform was benchmarked for this article.
- Gartner, August 26, 2025: task-specific agents in enterprise applications — the original forecast and its timeframe.
- Google Cloud, April 22, 2026: Gemini Enterprise updates — the vendor’s announcement of long-running agents and oversight features.
- Anthropic, December 19, 2024: Building effective agents — the architectural distinction between workflows and agents; tooling has since evolved.
Tags
Written by
Sourabh Gupta
Author at Teach AI Tools
Sourabh Gupta is responsible for Teach AI Tools. Research guides and documented firsthand reviews are identified separately. An author profile is not evidence of testing; look for sources, test records, and limitations in the article.
Full bio & editorial process →