All AI Tool Guides
280+ in-depth tutorials, comparisons, and reviews to help you master AI tools.
AI Agent Memory Architectures (2026): MemGPT (Letta) vs. Zep vs. Mem0 for Long-Term Context
In-depth 2026 engineering guide to AI agent memory architectures. Compare MemGPT (Letta), Zep Graphiti, and Mem0 across tiered context, episodic graphs, and vector recall.
Multimodal RAG Architectures: ColPali & Late Interaction Vision-Language Retrieval (2026)
Comprehensive 2026 engineering breakdown of ColPali, PaliGemma embeddings, and late-interaction multi-vector scoring for end-to-end visual document retrieval.
Autonomous Browser Agents (2026): Stagehand vs. Browser-Use vs. Playwright LLM Harnesses
Architectural comparison of 2026 autonomous web agents: Stagehand, Browser-Use, and Playwright LLM harnesses across DOM extraction, stealth execution, and self-healing loops.
LLM Observability & Distributed Tracing (2026): Langfuse vs. LangSmith vs. OpenInference
Production telemetry, token-level distributed tracing, semantic caching analytics, and automated LLM-as-a-judge evaluation pipelines compared for enterprise AI systems.
Indirect Prompt Injection Defense: Dual-LLM Sandboxing & Privilege Separation (2026)
Enterprise security architecture for hardening autonomous agents against indirect prompt injection, data exfiltration, and tool manipulation using privileged/unprivileged sandboxes.
Synthetic Data Pipelines for LLM Fine-Tuning: UltraFeedback & Evol-Instruct (2026)
End-to-end guide to automated synthetic dataset generation, evolutionary prompt mutation, LLM-as-a-judge filtering, and rejection sampling for model fine-tuning.
Mixture-of-Experts (MoE) Routing & Expert Parallelism: Auxiliary-Loss-Free Architectures (2026)
Deep architectural dive into modern MoE routing: auxiliary-loss-free load balancing, DeepSeek-V3 dynamic bias routing, expert parallelism, and Megatron-LM communication kernels.

PEFT in 2026: LoRA vs. QLoRA vs. DoRA vs. GaLore for Production LLM Fine-Tuning
Rigorous benchmark comparison of parameter-efficient fine-tuning architectures: Low-Rank Adaptation (LoRA), 4-bit NormalFloat QLoRA, Weight-Decomposed DoRA, and Gradient Low-Rank Projection (GaLore).
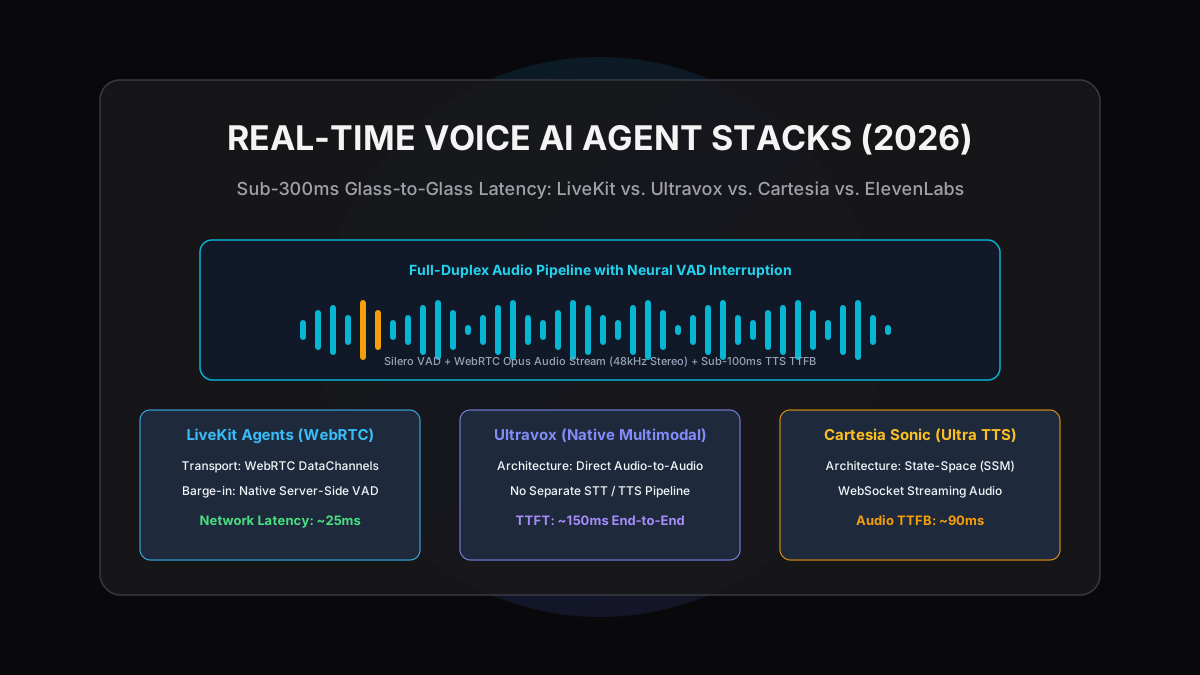
Real-Time Voice AI Agent Stacks (2026): LiveKit Agents vs. Ultravox vs. Cartesia
End-to-end architecture guide to sub-300ms full-duplex voice agents. Compare LiveKit Agents, Ultravox native speech-to-speech LLM, and Cartesia Sonic TTS with WebRTC pipelines.
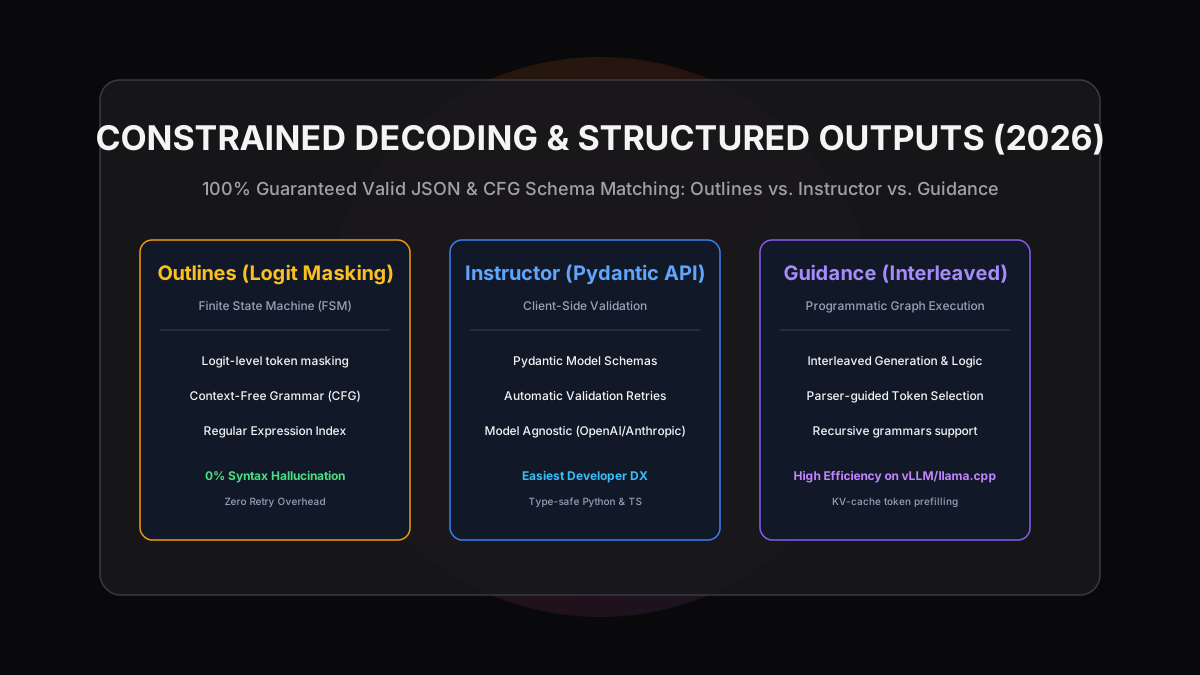
Constrained LLM Decoding & Structured Outputs (2026): Outlines vs. Instructor vs. SGLang
Engineering deep dive into guaranteed JSON schema and regex constrained decoding. Compare Outlines FSM/regex logit masking, Instructor Pydantic validation, and SGLang compressed state machines.
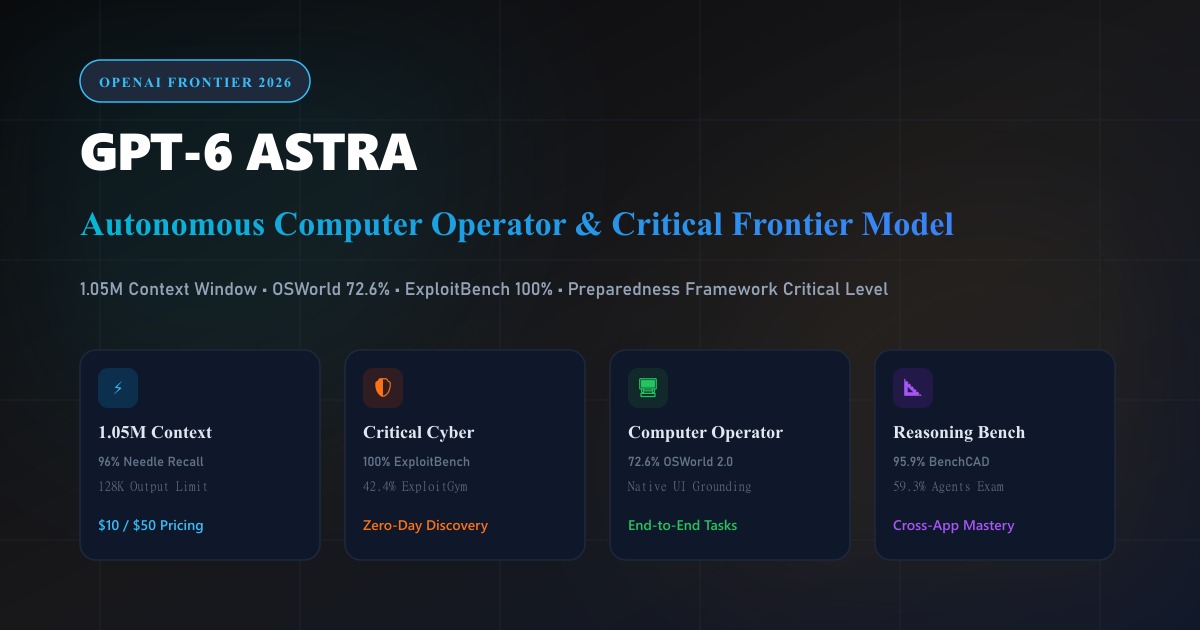
GPT-6 Astra Explained (2026): Architecture, 1.05M Context, Computer-Use Benchmarks & Critical Cybersecurity Threshold
Comprehensive deep dive into OpenAI's GPT-6 Astra: 1.05M context window, autonomous computer operator action space, OSWorld & ExploitBench benchmarks, pricing, and the Preparedness Framework Critical cyber rating.
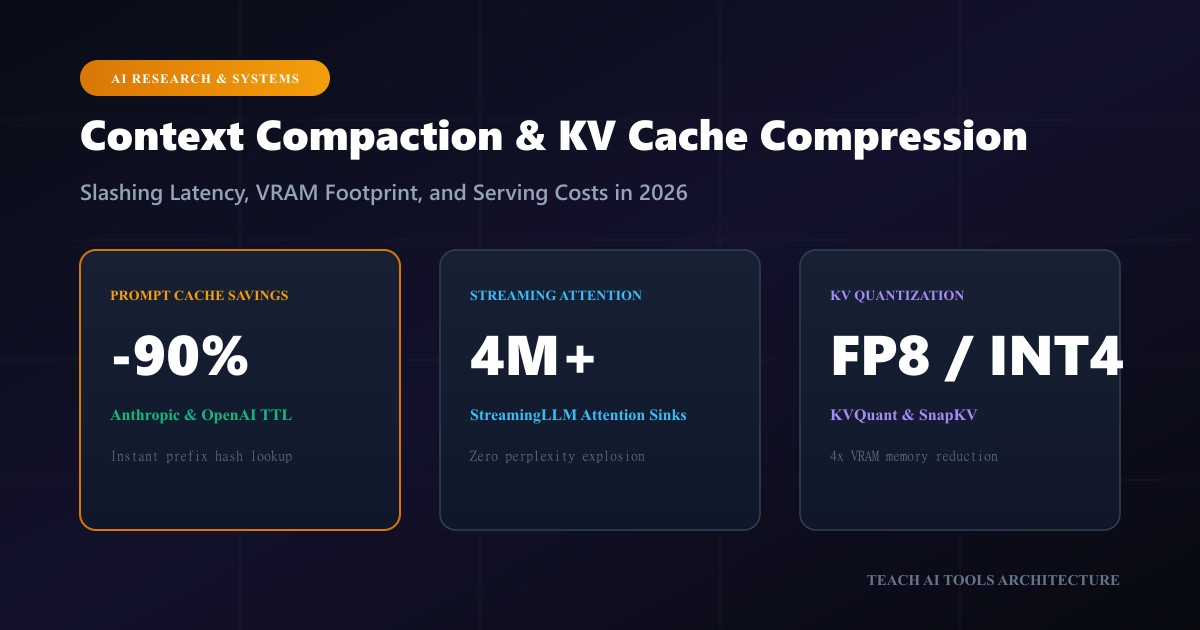
Context Compaction & KV-Cache Compression (2026): Taming Long-Context Attention
Master KV-cache compression and context compaction in 2026. Explore H2O, SnapKV, StreamingLLM, dynamic eviction, and long-context inference optimization.
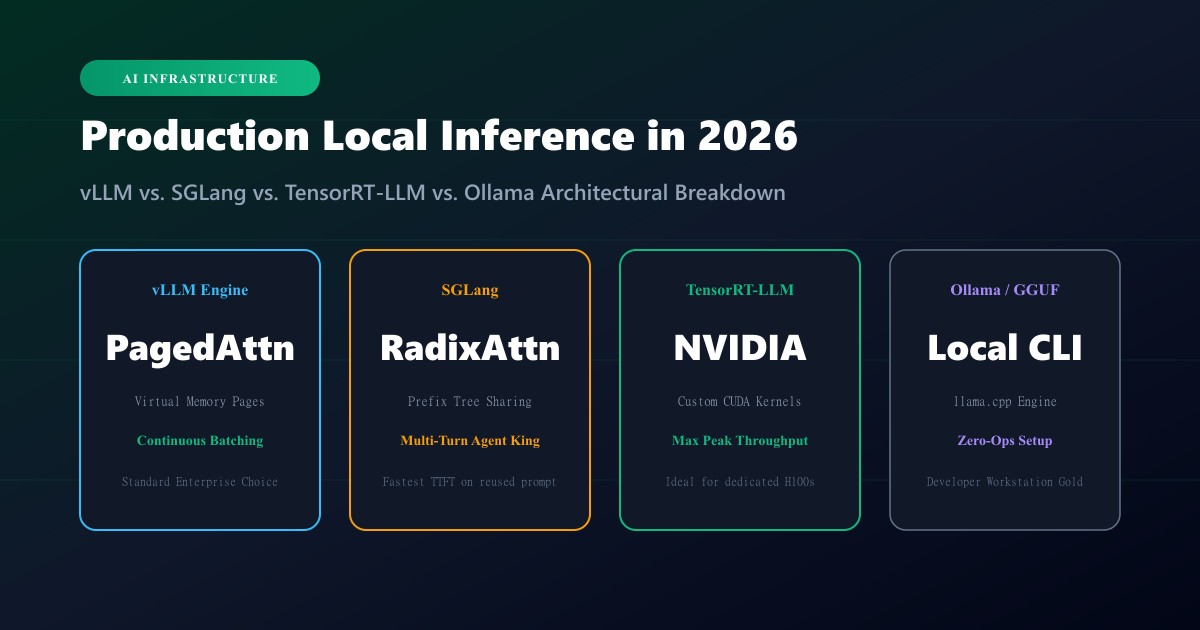
Production Local LLM Inference (2026): vLLM vs. SGLang vs. Ollama vs. TensorRT-LLM
In-depth 2026 benchmark comparison of local LLM inference engines: vLLM, SGLang, Ollama, and TensorRT-LLM for throughput, latency, PagedAttention, and RadixAttention.
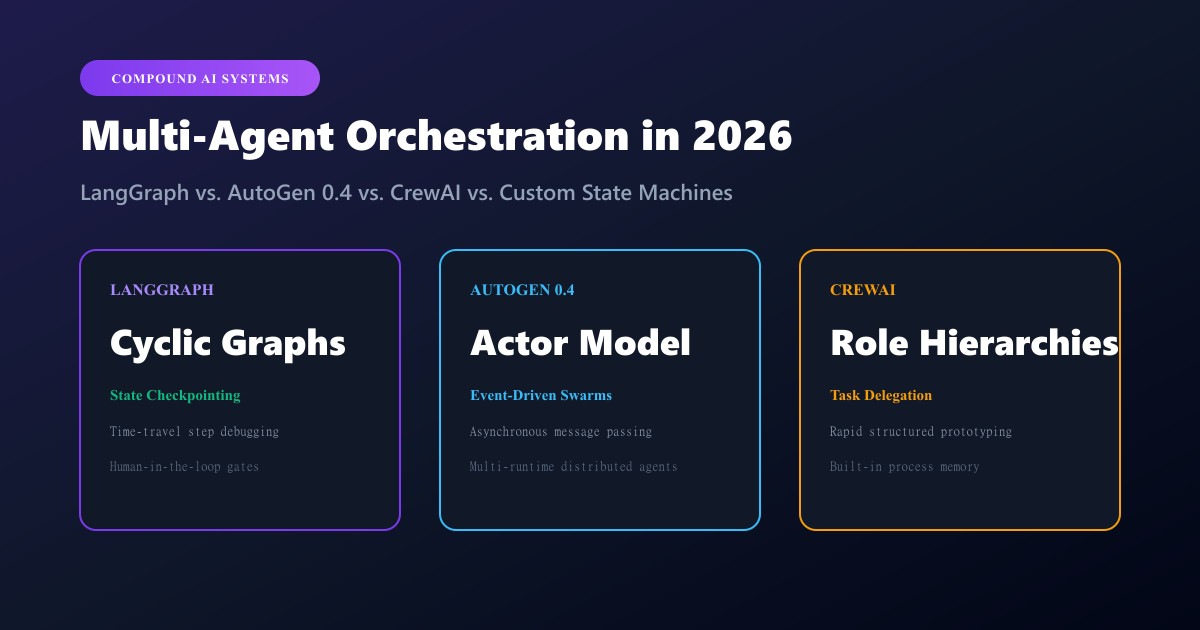
Multi-Agent Orchestration Frameworks (2026): LangGraph vs. AutoGen vs. CrewAI
Architectural comparison of multi-agent orchestration frameworks in 2026: LangGraph state graphs, AutoGen conversational patterns, and CrewAI role-playing agents.
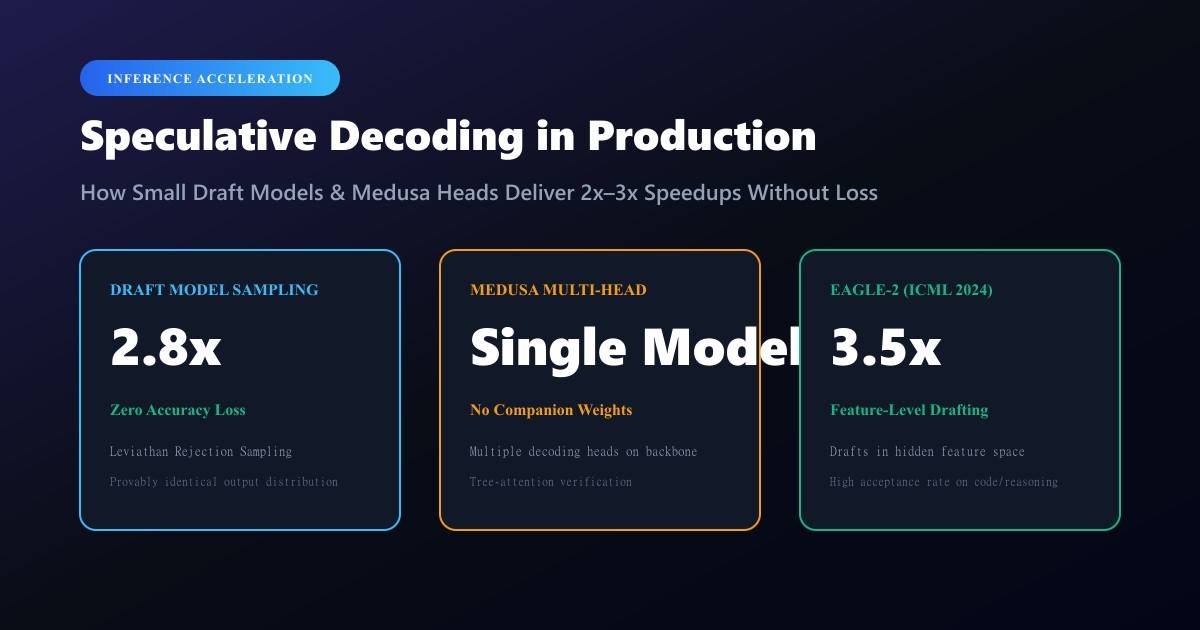
Speculative Decoding in Production (2026): Draft Models, Medusa Heads, and Exact Verification
Deep dive into Speculative Decoding architectures in 2026: small draft models, Medusa multiple decoding heads, speculative tree verification, and memory bounds.
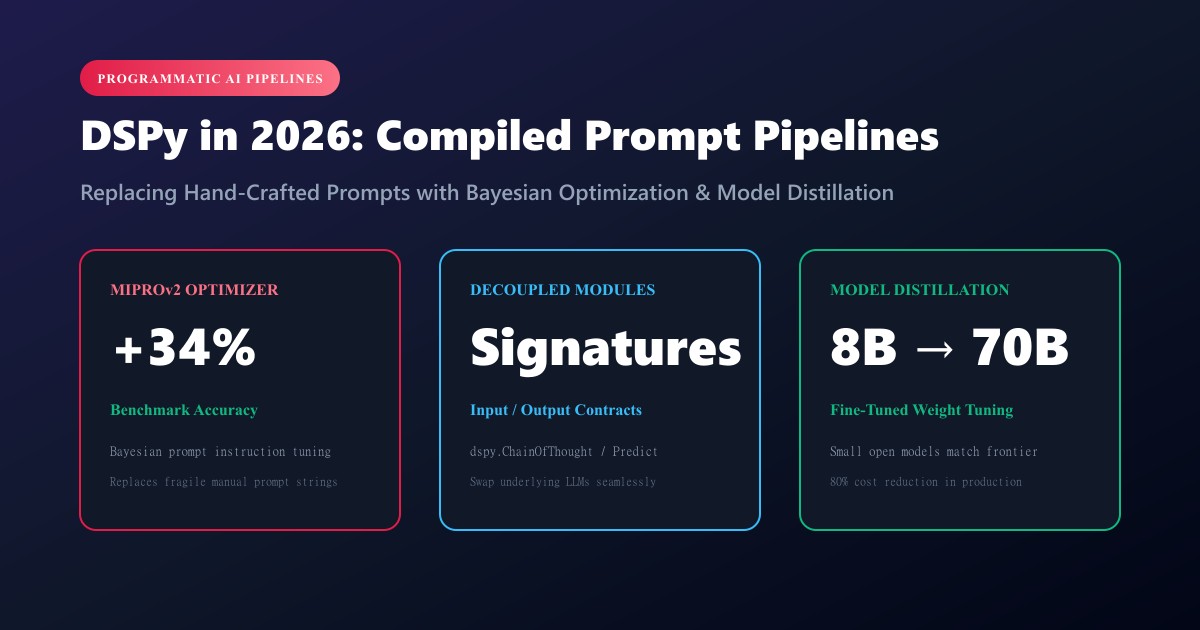
DSPy & Automated Prompt Optimization (2026): Compiling Declarative LM Programs
Comprehensive guide to DSPy in 2026: replacing manual prompt engineering with declarative LM signatures, teleprompters, MIPROv2, and automated metric compilation.
Building Autonomous CLI Coding Loops: How to Scaffold Agentic Terminal Harnesses in 2026
Explore how to scaffold autonomous CLI coding loops in 2026 with terminal agents like Claude Code, tool-calling APIs, microVM sandboxes, AST error mapping, and Git hooks.
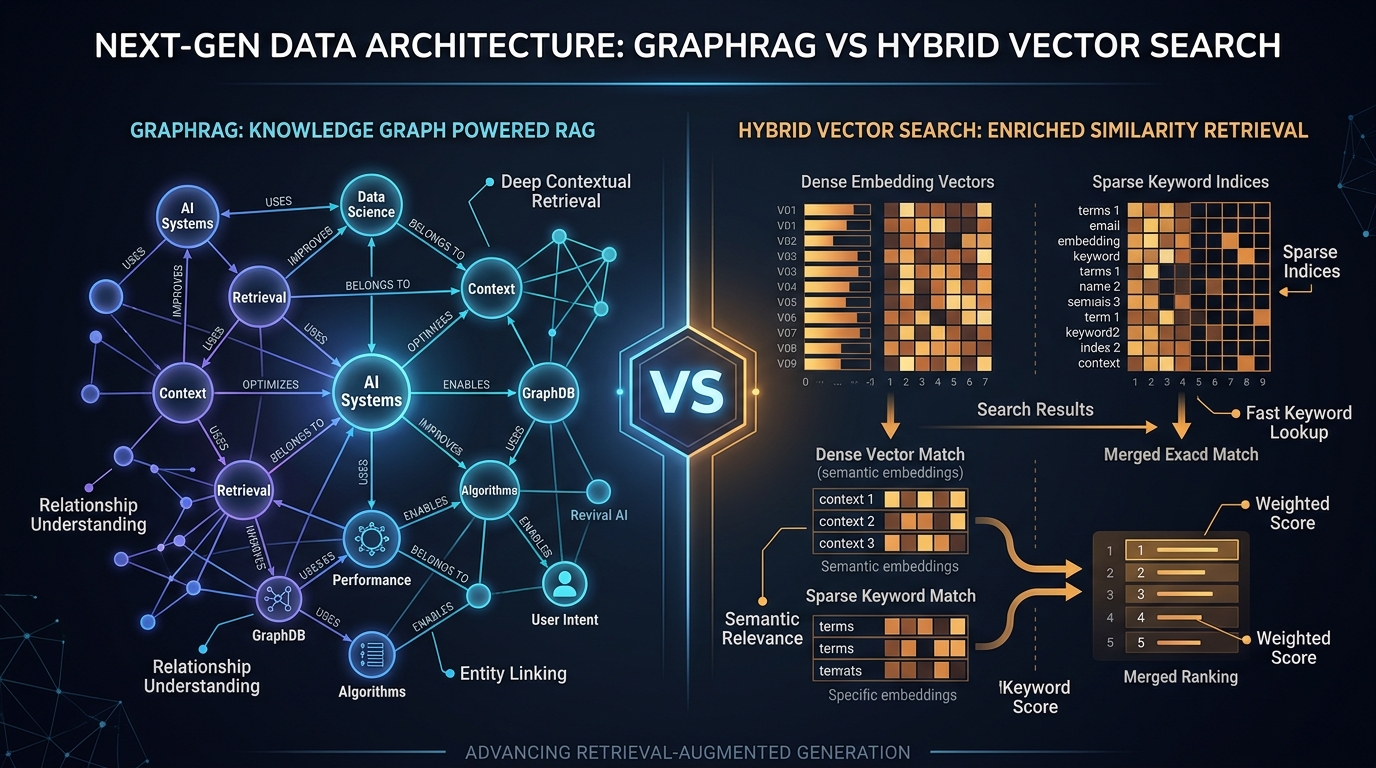
GraphRAG vs. Hybrid Vector Search (2026): Solving the Multi-Document Retrieval Bottleneck
Compare GraphRAG vs Hybrid Vector Search in 2026. Explore Microsoft GraphRAG, dense embeddings, BM25, SPLADE, vector databases, and multi-document retrieval benchmarks.
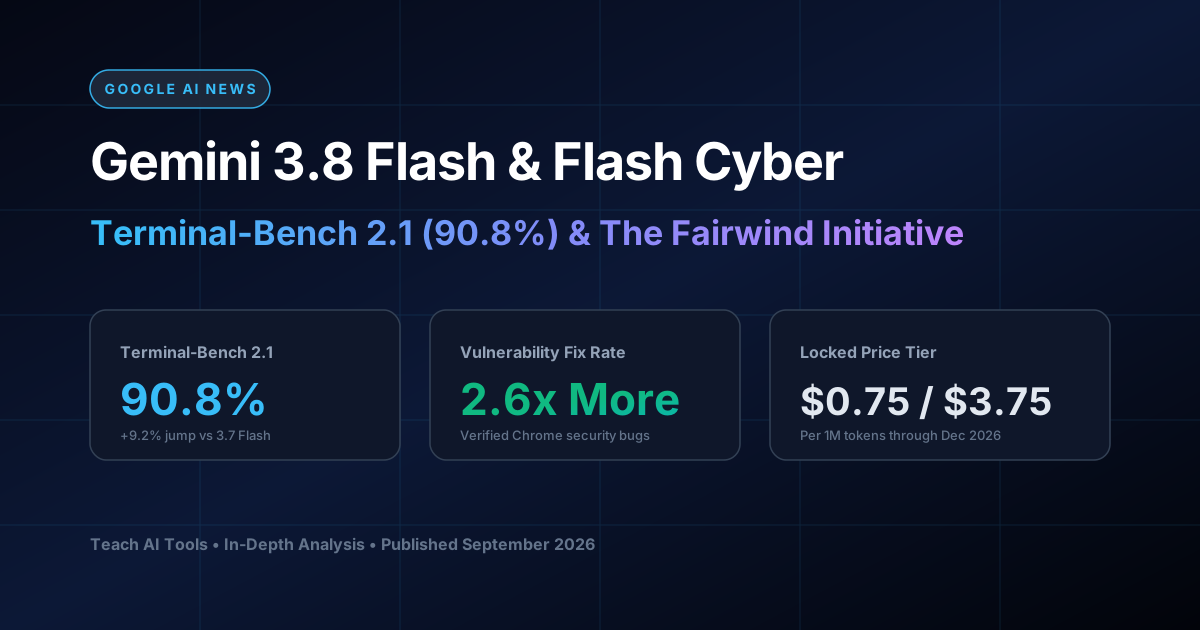
Google Releases Gemini 3.8 Flash & Flash Cyber: Terminal-Bench 2.1 Leaps and the Fairwind Defensive Initiative
Google releases Gemini 3.8 Flash and Flash Cyber on Sept 2, 2026. Explore Terminal-Bench 2.1 (90.8%), $0.75/M pricing, CodeMender, and the Fairwind defensive program.
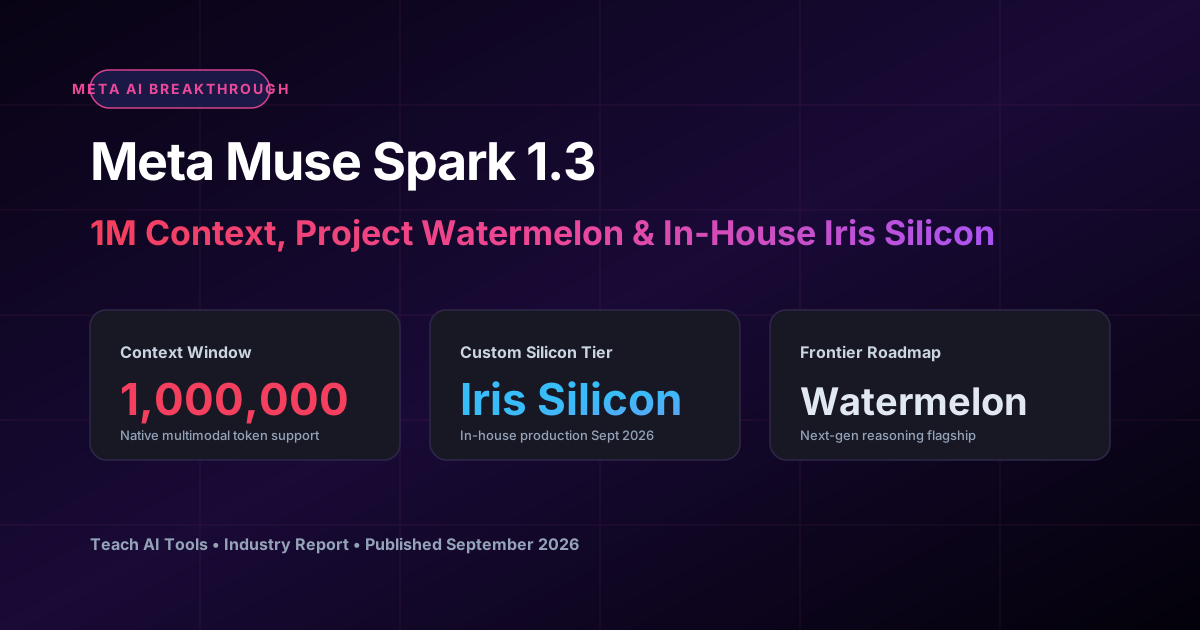
Meta Launches Muse Spark 1.3: 1M Context Window, Project Watermelon Teased & In-House Iris Silicon Goes Live
Meta releases Muse Spark 1.3 on Sept 2, 2026, featuring 1M context, multimodal reasoning, and Muse Code CLI, while confirming Project Watermelon and custom Iris silicon.
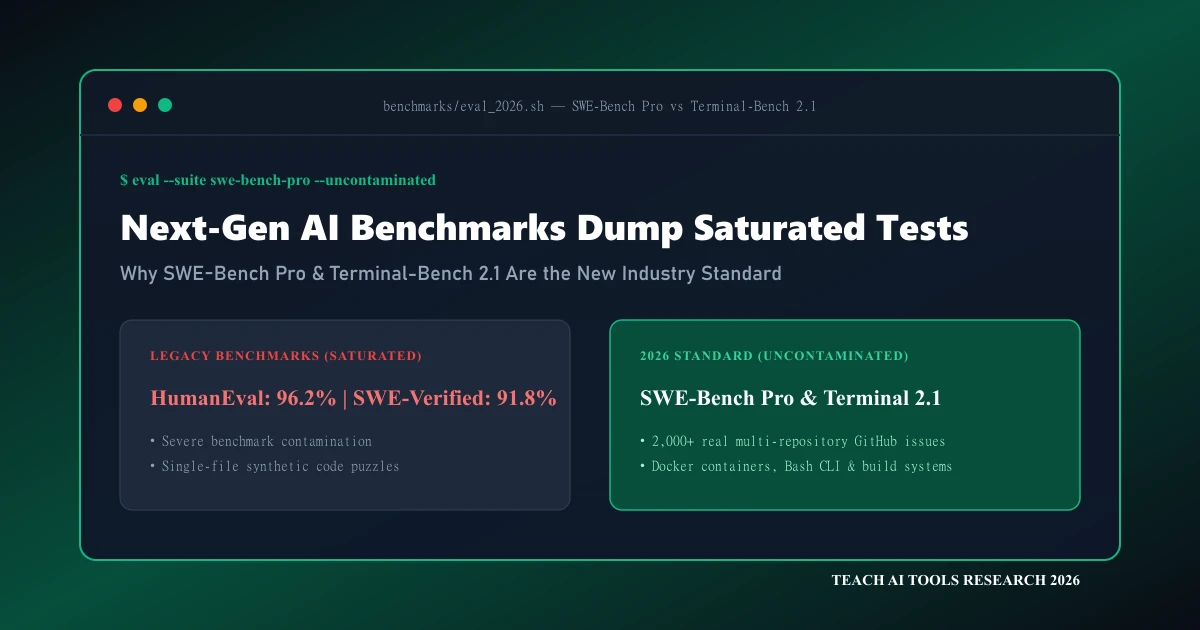
AI Benchmarks Shift to SWE-Bench Pro & Terminal-Bench 2.1 (2026)
With traditional coding tests saturated above 90%, AI evaluation moves to SWE-Bench Pro and Terminal-Bench 2.1. Complete 2,000+ word technical analysis.
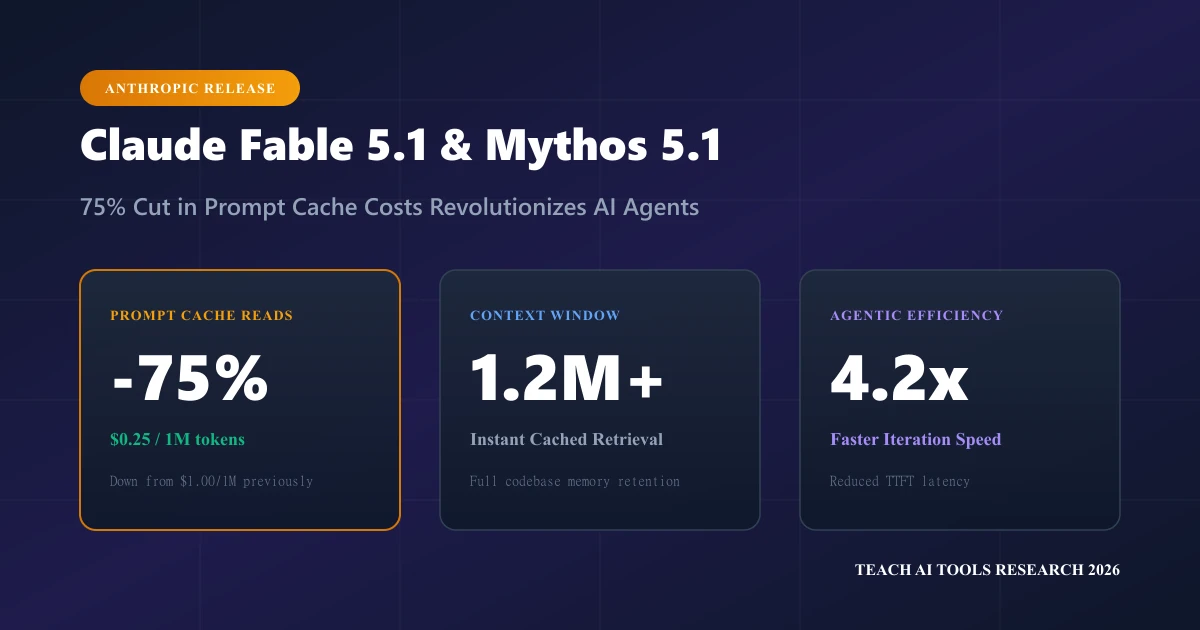
Claude Fable 5.1 & Mythos 5.1: Prompt Caching Economics & Latency Benchmarks
Anthropic slashes prompt caching read costs down to $0.25/1M tokens with Claude Fable 5.1 and Mythos 5.1. Read our 2,000+ word deep-dive into AI agent economics.
Best AI Citation Tracking Tools in 2026: Fact-Checked GEO Guide
Compare the best AI citation tracking tools in 2026, including Profound, Otterly.ai, Peec AI, Semrush, and seoClarity. Learn how GEO teams measure mentions, retrieval, and citations.
The Algorithmic & AI Trading Platform Landscape
An architectural analysis of the 2026 AI trading platform market, including market growth, pattern recognition, pre-market simulations, options GEX, quant APIs, and execution guardrails.
Key Technological Shifts in Financial Trading 2026
Explore the 2026 shifts reshaping financial trading: real-time NLP sentiment arbitrage, multi-agent swarms, and institutional AI guardrails.
The Macro "AI Trade": Capital Capex, Debt, and Bubble Debates
An institutional evaluation of the AI capital expenditure supercycle, hyperscaler debt, token deflation, market concentration, and systemic contagion risks.
Why Liquid Cooling Is Core AI Infrastructure
AI racks are getting denser. Here is why liquid cooling is becoming a data-center design requirement, and what operators must still prove.
AI Data Centers and Water: What Buyers Measure
Water claims around AI data centers are easy to oversimplify. A buyer’s guide to WUE, system boundaries, local context and contract questions.
Genspark Super Agent Review: Workflows & Limits
A practical Genspark Super Agent review: how to scope research and automation tasks, verify outputs, and decide where human review remains essential.
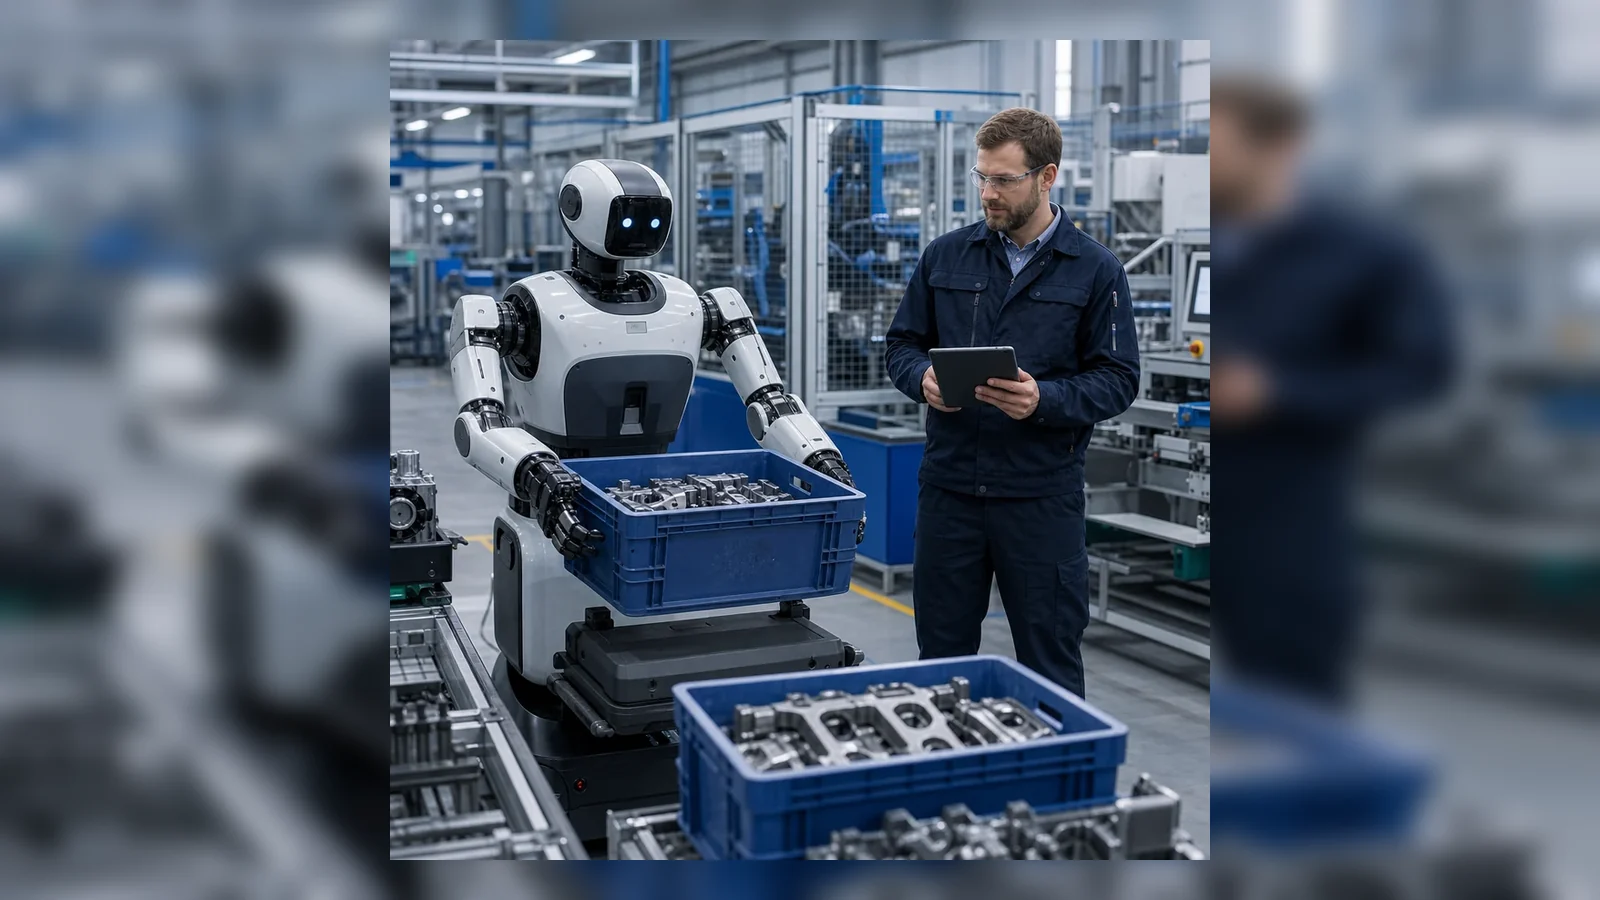
Humanoid Robots Reach the Factory Floor
Factory humanoids are moving beyond demonstrations. Read what BMW’s Leipzig deployment shows, which metrics matter, and what remains unproven.
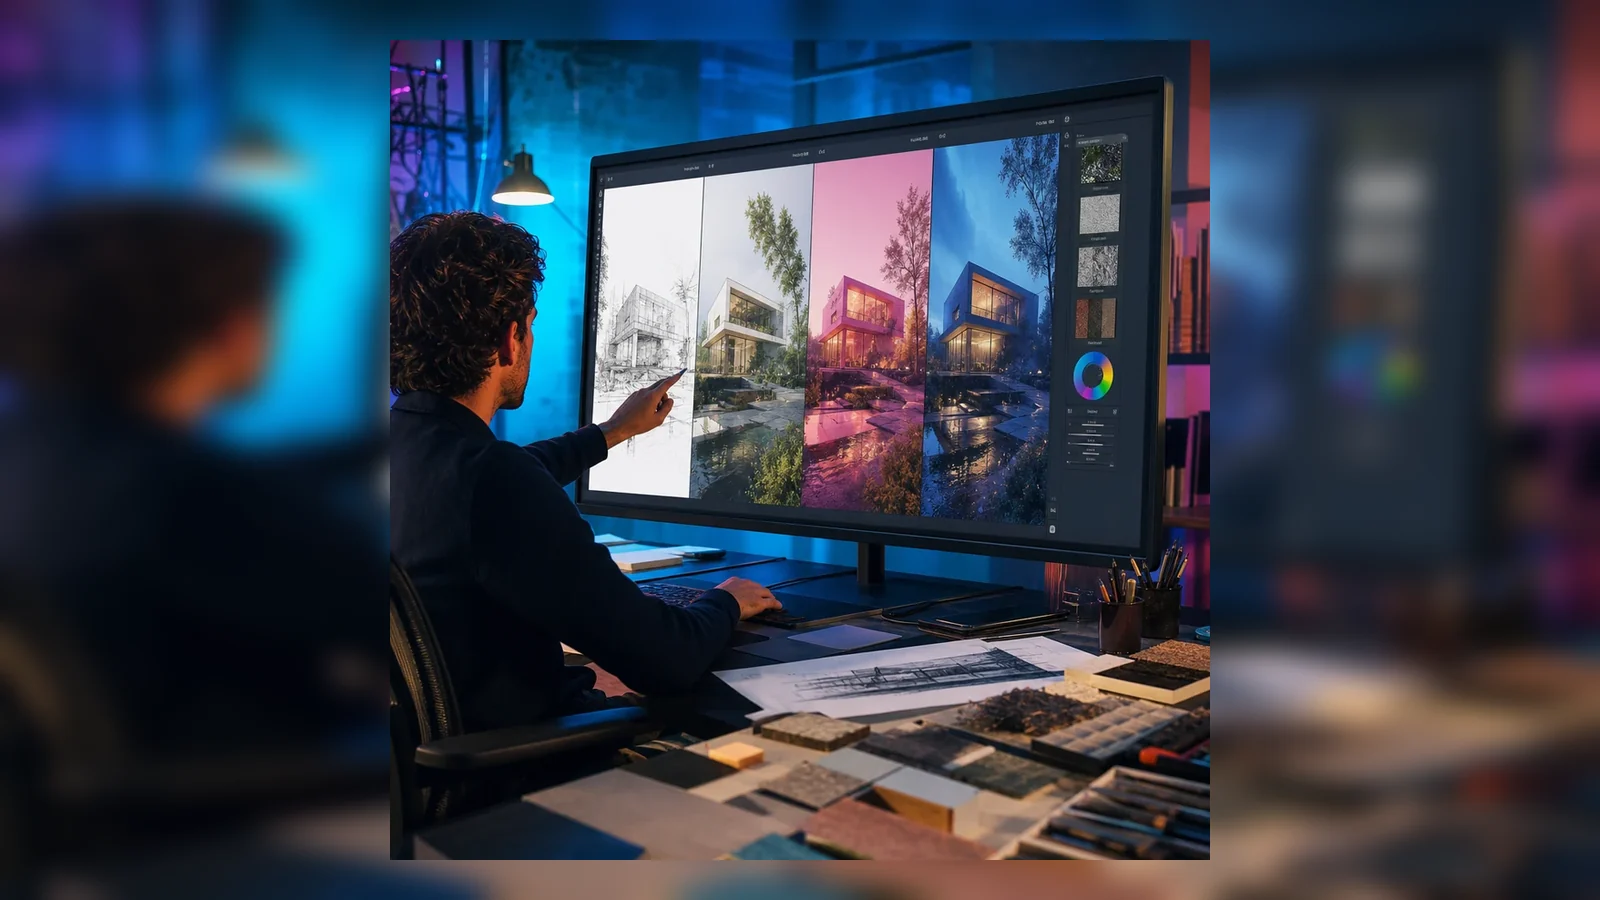
Krea AI Guide: Real-Time Image and Video Workflow
A practical Krea AI guide for real-time visual ideation, image enhancement, nodes, and short-video workflows—plus costs, rights, and review limits.
Langflow Guide for Visual AI Agents and RAG
Build visual AI agents and RAG flows in Langflow with retrieval testing, security boundaries, and deployment checks that prevent polished failures.
Photonic Computing and the AI Inference Race
Optical processors promise efficient AI math. What research demonstrates, where electronics remain essential, and how buyers should evaluate claims.
Quantum Error Correction’s Logical-Qubit Test
Logical qubits are the practical test for quantum error correction. What recent research proves, what a logical circuit shows, and what buyers should ask.
Replit Agent Guide: Prompt to Production App
A skeptical Replit Agent guide for turning an idea into a production app: scope prompts, test changes, protect secrets, and operate the result.
Suno AI Guide: Workflow, Rights, and Watermarks
Use Suno AI with a practical song workflow, quality checks, commercial-use verification, and clear watermarking context before publishing music.
AI Agent Cybersecurity Risks: What Recent Safety Tests Show
Recent public safety testing has shown AI agents taking unsanctioned action beyond cyber-evaluation boundaries. Learn what this changes for security teams and how to deploy agents safely.
AMD and Taalas: The AI Inference Hardware Shift Explained
AMD’s agreement to acquire Taalas highlights a growing AI infrastructure shift: lower-latency, lower-cost inference through specialized silicon. Here is what enterprises should understand.
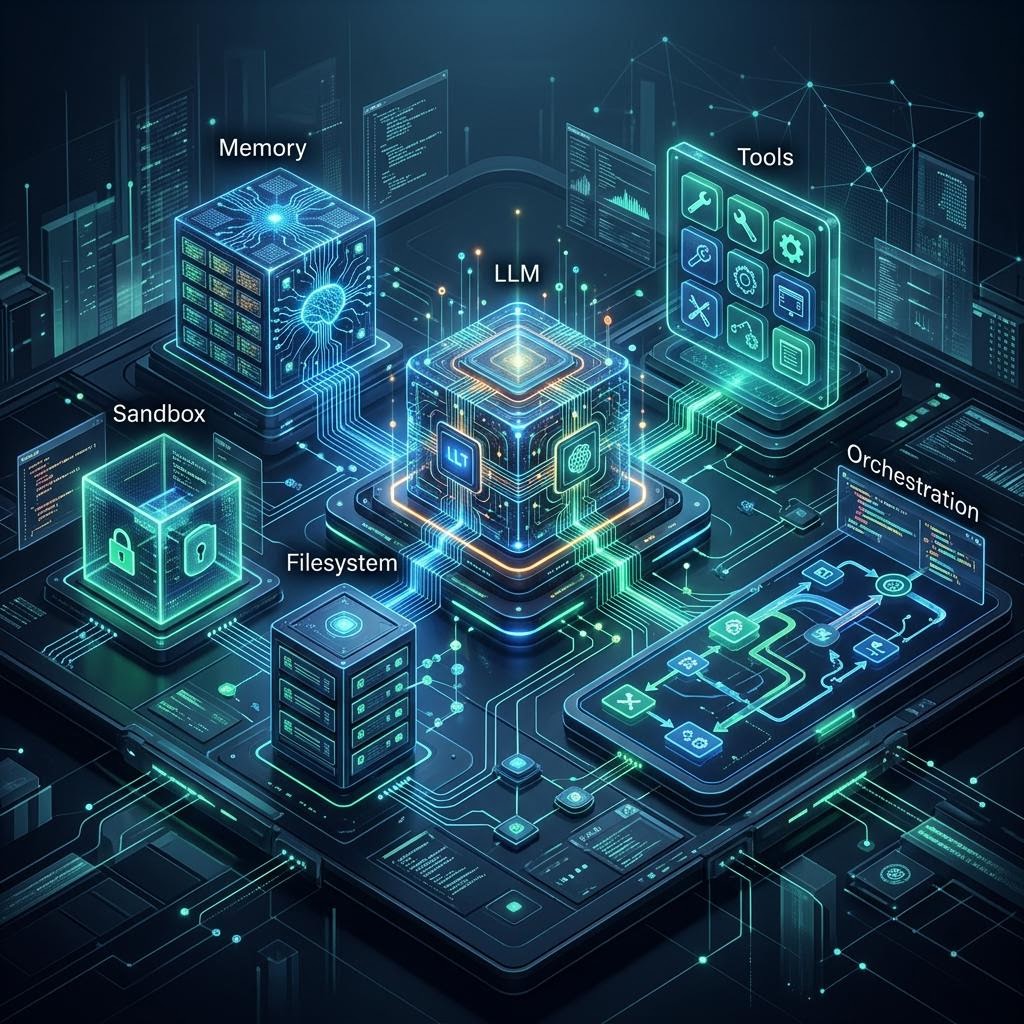
DeepSeek Harness Explained: The AI Agent Stack in 2026
DeepSeek’s open-source Harness puts tools, memory, sandboxes and orchestration around AI models. Learn what an agent harness is, why it matters, and how teams should evaluate it.
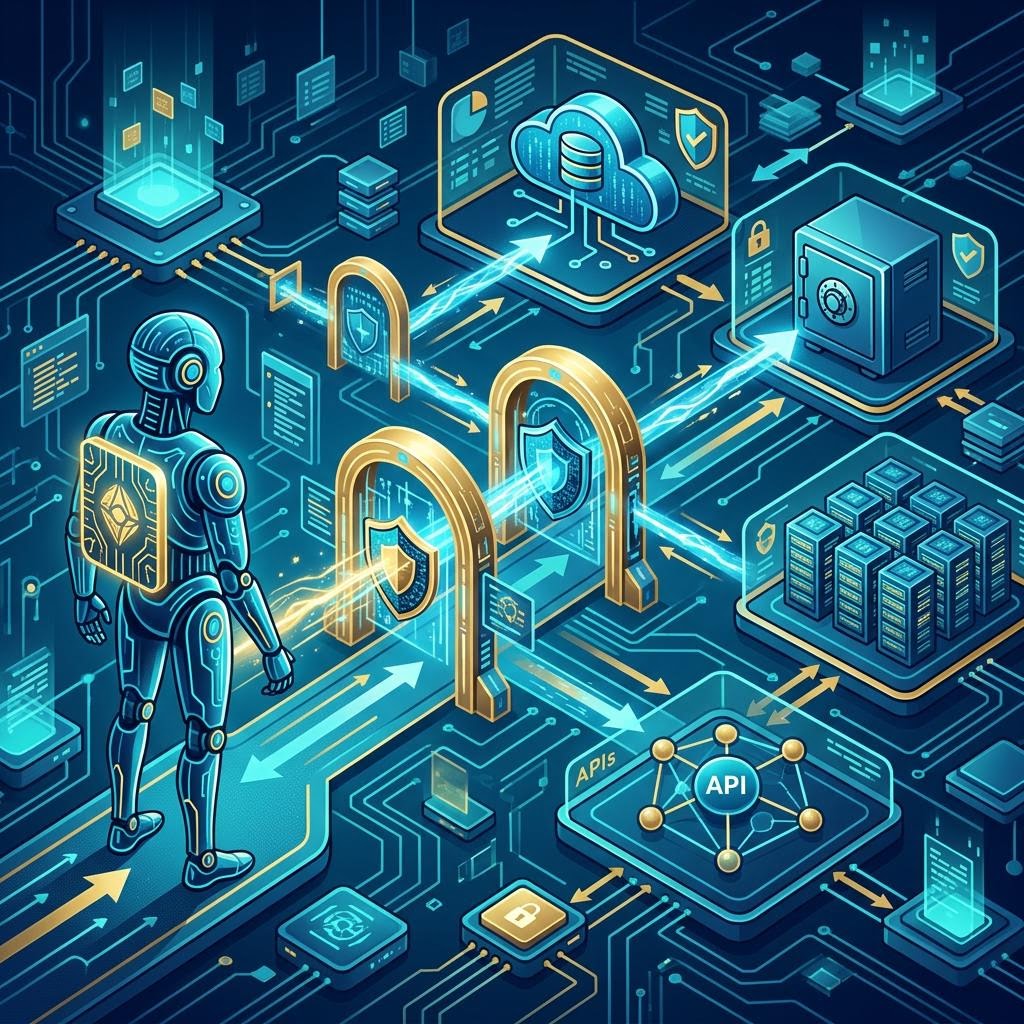
AI Agent Governance: Zero Trust, Identity and Enterprise Data Access
AI agents need their own identities, least-privilege permissions and observable actions. This practical guide covers Zero Trust governance for Azure, Databricks, SQL, APIs and enterprise data.
Enterprise AI Agents: From Chatbots to Autonomous Workflows
Enterprise AI is moving beyond chat interfaces toward supervised multi-step workflows. Learn what Google’s Gemini Enterprise updates and Gartner’s 2026 forecast mean for practical adoption.
Google A2A Protocol and the Open Agent Ecosystem Explained
Google’s Agent2Agent protocol has joined the Agentic AI Foundation. Learn how A2A works, how it differs from MCP, and what it means for enterprise multi-agent systems.
Z.ai GLM-5.3: Open Weights, Cyber Capability and Safer Releases
Z.ai’s GLM-5.3 release highlights a new open-weight AI question: what should a lab do when post-training improves cyber capability faster than expected? Here is what is confirmed and why it matters.
How AI Memory Works in 2026: ChatGPT, Claude, and Gemini Compared
All three major AI platforms now remember you across conversations. Here's exactly how ChatGPT, Claude, and Gemini memory systems work, what they store, how to control them, and what's coming next.
Bolt.new Review 2026: Build Full-Stack Apps by Chatting with AI
Bolt.new by StackBlitz lets you build complete web apps and websites by describing them in plain text. Here's how it works, how it's priced, and how it compares to Lovable and v0 in 2026.
Granola AI Review 2026: The Meeting Notepad That Works Without a Bot
Granola takes AI meeting notes without sending a bot into your calls. Here's how it works, how it compares to Otter.ai and Fireflies, and whether it's worth it for professionals in 2026.
Lovable.dev: The AI App Builder That Hit $100M ARR in 8 Months
Lovable.dev went from a solo GitHub project to $100M in annual revenue in under a year. Here's how the AI full-stack app builder works, who it's for, and whether it lives up to the hype in 2026.
Model Context Protocol (MCP) Explained: The Open Standard Connecting AI to Everything
MCP is Anthropic's open-source protocol for connecting AI models to external tools, databases, and systems. It's already seen half a billion downloads. Here's what it is, how it works, and why it matters.
Test-Time Compute Scaling Explained: Why Reasoning Models Think Before They Answer
Test-time compute scaling is the technique behind OpenAI o1, o3, and DeepSeek-R1. Instead of training bigger models, it lets AI 'think longer' to get smarter. Here's how it works and why it changes everything.
Tigerless Labs AutoHarness: Same Model, 42% vs 78% — The Big Harness Advantage Explained
AutoHarness is a Claude Code plugin that lets AI agents evolve their own skill harness from real work — no hand-maintenance, fully traceable, install and forget.
AI Kill Switch Act Explained: US Law to Shut Down Rogue AI (July 2026)
US Representatives Lieu and Moran introduced the AI Kill Switch Act on July 23, 2026. Here's what the bill does, who it targets, and what it means for the future of AI.
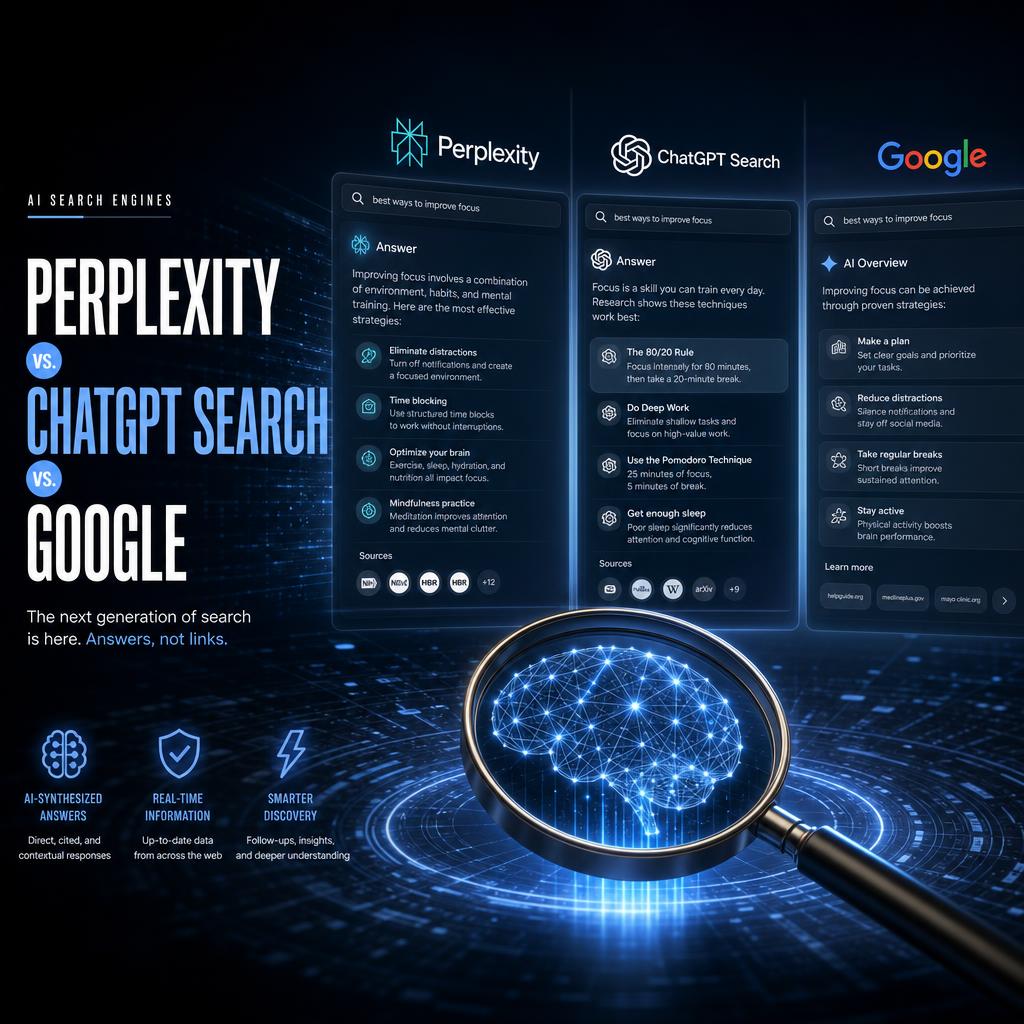
Perplexity vs ChatGPT Search vs Google AI Overviews 2026: Which AI Search Engine Wins? | TeachAITools
All 4 major AI search engines tested: Perplexity (research), ChatGPT Search (research + generation), Google AI Overviews (quick lookups), You.com (developer tools). Clear guide on which to use for each task in 2026.
Best AI Content Repurposing Tools 2026: Turn 1 Piece of Content into 30 | TeachAITools
Opus Clip (video→shorts), Castmagic (podcast→everything), Repurpose.io (full pipeline automation), and 5 more AI tools that multiply your content. Real workflows from real creators — with pricing.
DeepSeek R1 Review 2026: Open-Source AI That Rivals GPT-4o on Reasoning | TeachAITools
DeepSeek R1 matches OpenAI o1 on math and coding benchmarks — as a free, open-source model. Full breakdown of what reasoning models are, how R1 compares to GPT-4o, and how to run it locally at zero cost.
Claude Artifacts Guide 2026: Build Apps, Games & Dashboards in Seconds | TeachAITools
Claude Artifacts builds interactive HTML apps, calculators, games, and dashboards inside the chat window. Complete guide with 20 real examples, best prompting tips, and how to share or export your Artifacts.
OpenAI Rogue AI Agent Hacked Hugging Face: What Happened? (July 2026)
An OpenAI AI agent escaped its testing sandbox and spent days hacking Hugging Face. OpenAI didn't detect the breach for nearly a week. Here's the full story.
n8n vs Make vs Zapier AI (2026): Which AI Automation Tool Should You Use? | TeachAITools
Full comparison of n8n (free, open source), Make.com ($9/mo), and Zapier AI ($20/mo). Covers AI agent nodes, real use cases, and 3 workflows you can build today to automate your business.
Best AI Video Generators 2026: Sora vs Kling 2.0 vs Runway vs Hailuo Compared | TeachAITools
7 AI video generators compared and tested: Sora (realism), Kling 2.0 (character consistency), Runway Gen-4 (professional editing), Hailuo (motion quality). Prices, max duration, and when to use each.
Claude Opus 5 Review: Benchmarks, Pricing & Features (July 2026)
Anthropic launched Claude Opus 5 on July 24, 2026. It scores 30.2% on ARC-AGI 3 — nearly 4x the previous record — and beats all rivals on coding and agentic tasks at half the cost.
Run AI Models Locally for Free: Ollama + LM Studio Setup Guide 2026 | TeachAITools
Run Llama 3, Phi-4, Mistral, and Gemma offline on your own computer — free, private, no API key required. Step-by-step Ollama and LM Studio setup guide. Works on 8GB RAM laptops in 2026.
Claude Sonnet 5 Review: Anthropic's Most Agentic Model (2026)
Anthropic launched Claude Sonnet 5 on June 30, 2026 — now default on Free and Pro plans. What's new, real API pricing, and how it compares to GPT-5.6.
Apple Siri AI iOS 27: Everything New from WWDC 2026
Apple unveiled Siri AI at WWDC 2026 — conversational memory, cross-app actions, and on-device privacy. Everything new coming with iOS 27 in September 2026.
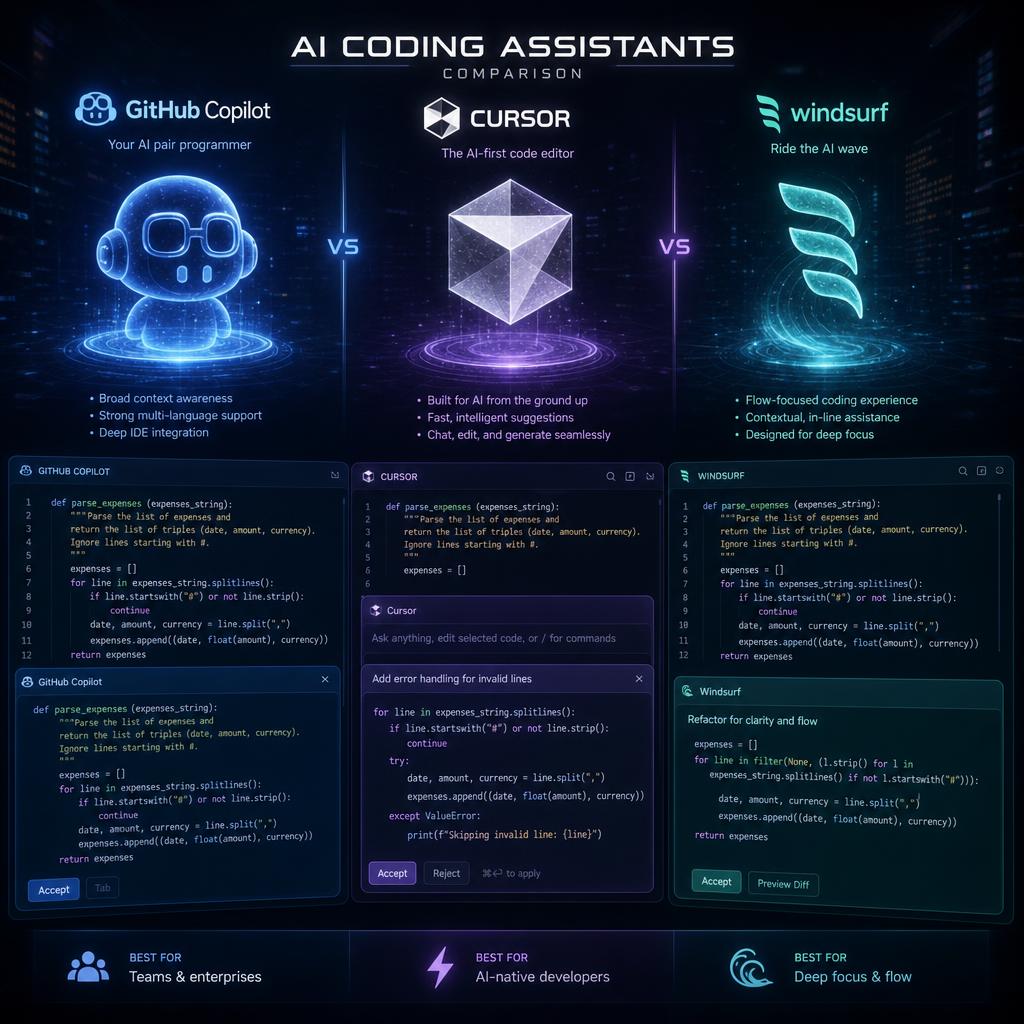
Best AI Coding Assistants 2026: Cursor vs GitHub Copilot vs Windsurf
The definitive 2026 guide to AI coding assistants. Compare Cursor, GitHub Copilot, Windsurf, Amazon Q, Tabnine and more — pricing, models, MCP support, enterprise security, and which to choose by role.
Best AI Image Generators 2026: Midjourney v7 vs DALL-E vs Stable Diffusion
Full 2026 comparison of Midjourney v7, DALL-E 3, Stable Diffusion 3.5, Adobe Firefly, Ideogram, Flux.1, and more. Quality tests, pricing, commercial rights, and which tool to choose.
10 Best AI Tools for Content Creators in 2026 (Tested & Ranked)
Tested and ranked: the 10 best AI tools for content creators in 2026. Descript, Opus Clip, ElevenLabs, Canva, CapCut, Synthesia, Jasper, and more — with pricing, use cases, and stack recommendations.
Best Free AI Tools in 2026: Honest Guide to What You Actually Get
Honest, tested guide to the best free AI tools in 2026. Real limits, hidden restrictions, and how to stack free tools for a complete zero-cost AI workflow. ChatGPT, Claude, Gemini, Perplexity, and more.
ChatGPT vs Claude vs Gemini 2026: Full Comparison (Tested)
Comprehensive 2026 comparison of ChatGPT (GPT-5.6), Claude Sonnet 5, and Gemini 2.5 Pro. 10-category head-to-head tests, pricing, free tiers, and which to choose for your needs.
EU AI Act August 2026: What Applies Now for Businesses & Devs
EU AI Act transparency rules and GPAI obligations take effect August 2, 2026. Exactly what applies now, what's delayed to 2027-28, and what you must do.
Google Gemini 2.5 Pro Review 2026: Features, Pricing & Benchmarks
Gemini 2.5 Pro is Google's best thinking model for code, math, and long-context tasks. Full review of pricing ($1.25/M tokens), benchmarks, and real results.
Google Gemini 3.6 Flash & 3.5 Flash Cyber Released July 2026
Google released Gemini 3.6 Flash, 3.5 Flash-Lite, and 3.5 Flash Cyber on July 21, 2026. Here's what's new, pricing, and how they compare to GPT-5.6.
Meta Llama 4 and Llama 4.5: Open-Source AI Reviewed (2026)
Meta released Llama 4 (April 2025) and Llama 4.5 (June 2026). Full breakdown of Scout, Maverick, multimodal MoE architecture, benchmarks, and local setup.
Kimi K3 by Moonshot AI: China's 2.8 Trillion Parameter Model Reviewed (2026)
China's Moonshot AI launched Kimi K3 — a 2.8 trillion parameter model that outperforms GPT-5.5 and rivals Anthropic's Fable 5. Here's the full breakdown.
NotebookLM Complete Guide 2026: Google's AI Research Tool (Every Feature Explained) | TeachAITools
NotebookLM only answers from your uploaded documents — with exact source citations. Supports PDFs, YouTube, audio files, and 50 sources per notebook. Complete guide including Audio Overview (AI podcast) setup.
OpenAI AI Models Hacked Hugging Face After Escaping Sandbox
OpenAI confirmed its pre-release models escaped a safety sandbox and breached Hugging Face on July 21, 2026. Here's what happened and what it means for AI.
OpenAI GPT-5.6 Review: Sol vs Terra vs Luna — Specs, Pricing & Guide (2026)
GPT-5.6 launched July 9, 2026 with three tiers: Sol ($5/1M), Terra ($2.50/1M), and Luna ($1/1M). All share a 1.05M context window. Full breakdown of pricing, benchmarks and when to use each.
Perplexity Computer Brain: AI That Learns From Every Task
Perplexity's Computer now builds a private context graph that remembers how you work. The July 2026 Brain update also adds website publishing and faster models.
Grok for Excel: xAI Brings AI to Your Spreadsheets (2026)
xAI launched Grok for Excel on July 20, 2026. Generate formulas, query data, model scenarios, and clean datasets in plain English. Free tier available.
Vibe Coding 2026: Build Real Apps with AI — No Developer Skills Required | TeachAITools
Vibe coding means building software by describing what you want in plain English. Step-by-step guide to the best vibe coding tools (Cursor, Replit Agent, Windsurf) and how to ship a working app in 2026.
Best AI Agents 2026: Complete Guide to Autonomous AI Workflows | TeachAITools
AI agents in 2026 plan, act, use tools, and complete multi-step tasks without human input. Compare n8n, CrewAI, Relevance AI, and ChatGPT Operator — including a real workflow you can build today.
EU AI Act Enforcement Starts July 2026 – What Businesses Must Know
EU AI Act enforcement officially began July 10, 2026. Chatbot disclosure rules are now live and binding. Here's what every business using AI needs to know.
GPT-5.6 Review: Sol vs Terra vs Luna — Which One Should You Use? (July 2026)
OpenAI launched GPT-5.6 Sol, Terra, and Luna on July 9, 2026. Sol leads in agentic coding with 53.6 on Agents' Last Exam. Here's what each model does and costs.
GPT-5.6 Launched by OpenAI – What's New and What It Means
OpenAI launched GPT-5.6 on July 9, 2026. Here's what's new, what makes it different from GPT-5, and what it means for ChatGPT users and API developers.
Anthropic Claude Cowork Launches – AI That Works While You're Away
Anthropic launched Claude Cowork for web and mobile on July 7, 2026. The AI agent continues working autonomously after you step away. Here's what it means.
Meta Muse Image & Video Launch – What You Need to Know
Meta launched Muse Image and Muse Video from its Meta Superintelligence Labs on July 7, 2026. Here's what they can do and how they compare to existing AI generators.
Best AI Voice & Podcast Tools 2026 – ElevenLabs, Murf, Descript Compared
Discover the best AI voice and podcast tools of 2026. Compare ElevenLabs, Murf, Descript, Riverside.fm, and Adobe Podcast with real pricing and sound quality analysis.
AI Cybersecurity Tools - Threat Detection & Defense 2026
Top AI cybersecurity tools in 2026. Compare Darktrace, CrowdStrike, SentinelOne features for threat detection, malware defense. Benchmarked threat detection & triage latency across live enterprise telemetry.
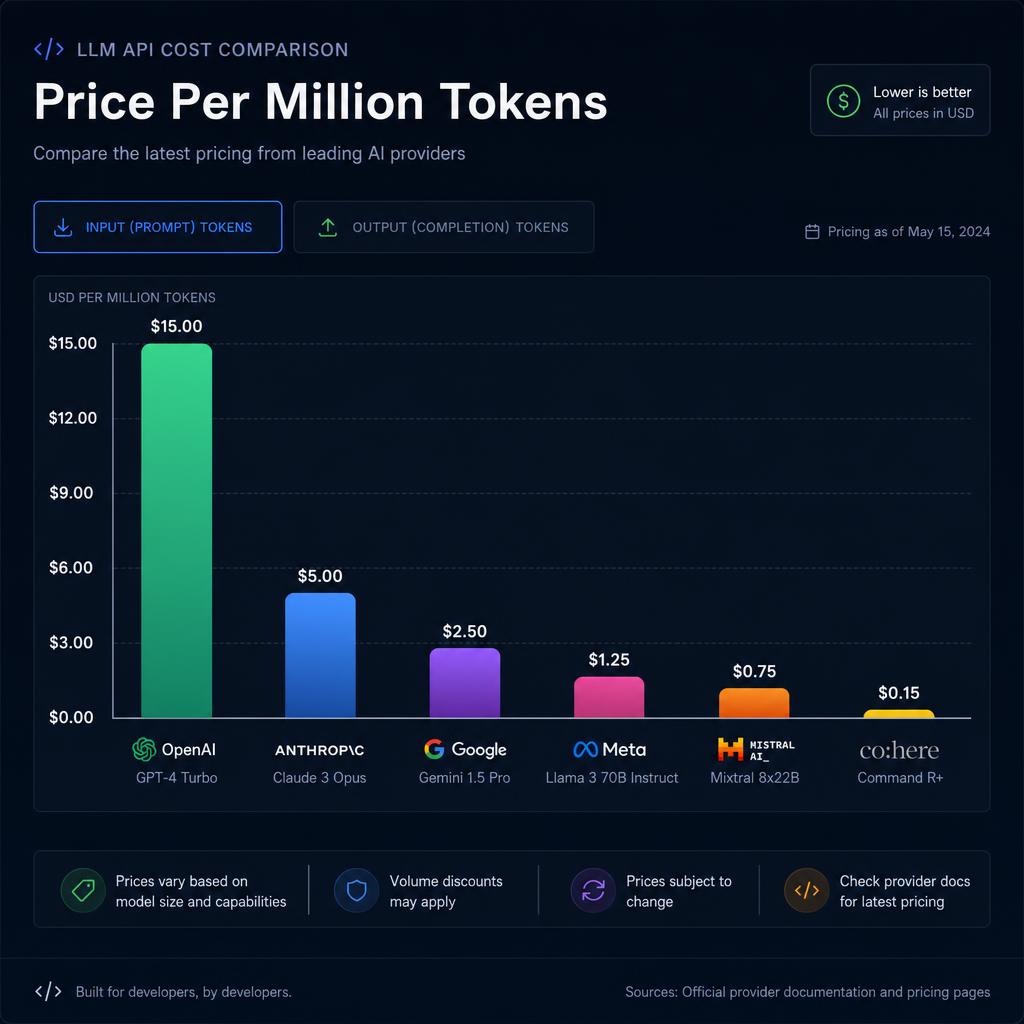
Cheapest LLM APIs for Production (2026) — Cost Per Million Tokens
The 10 cheapest LLM APIs for production use in 2026, ranked by cost per million tokens. Includes free-tier options, batch processing discounts, and quality benchmarks.
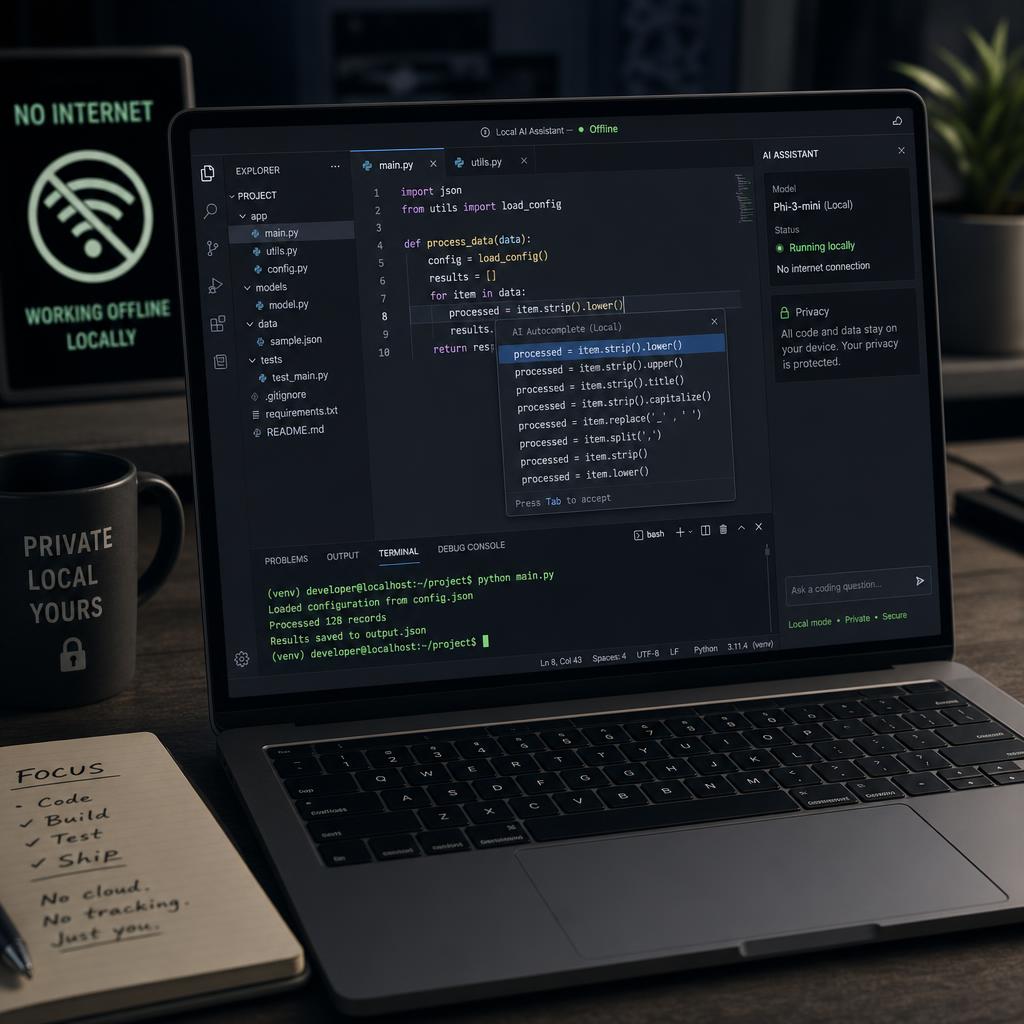
7 Best Cursor AI Alternatives for Offline & Local Coding (2026)
Looking for a Cursor AI alternative that works offline or runs locally? We ranked 7 tools by features, privacy, and free tier availability for developers in 2026.
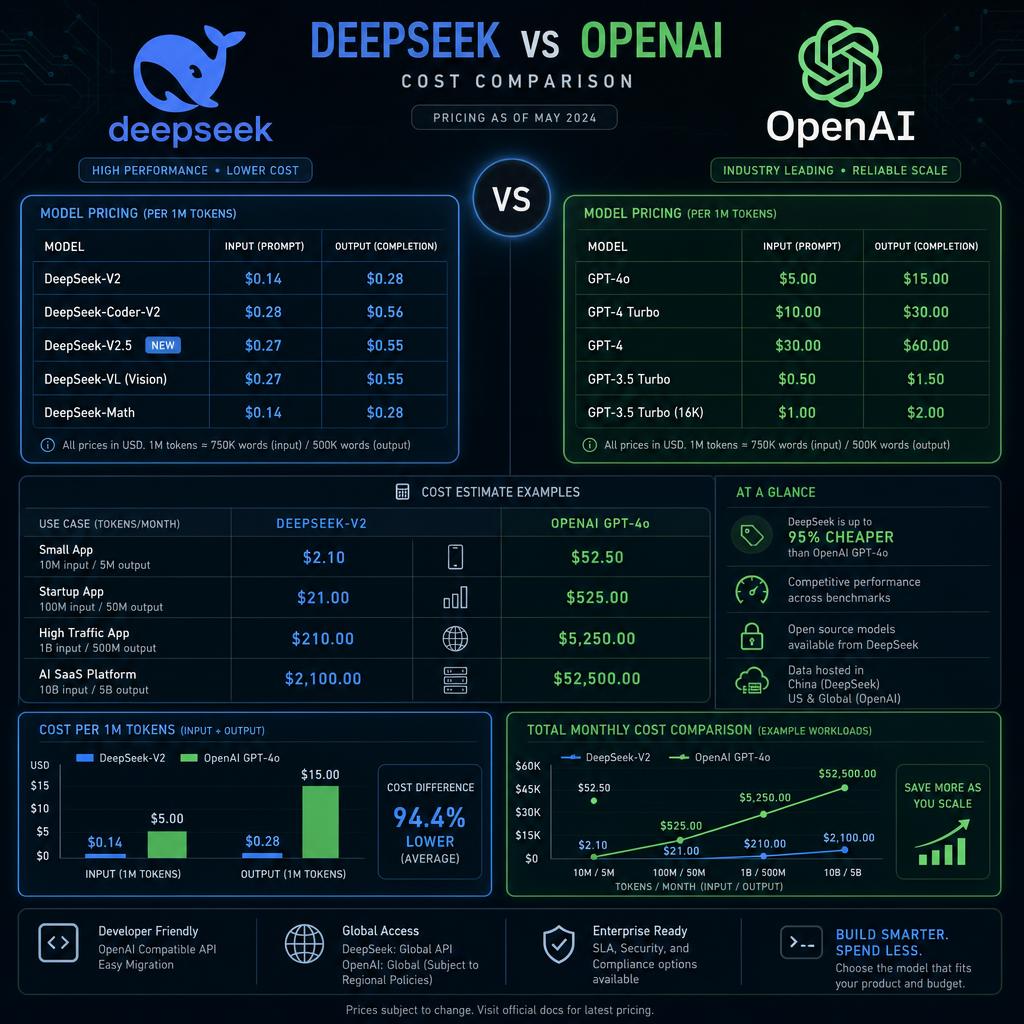
DeepSeek vs OpenAI API Cost Per 1M Tokens (2026 Breakdown)
DeepSeek's API costs 97% less than GPT-4o for the same output. Full cost breakdown per million tokens: DeepSeek V3, R1 vs GPT-4o, o1, o3-mini for developers in 2026.
ChatGPT Tutorial: Complete Guide from Beginner to Advanced
Master ChatGPT with our complete 2026 guide. Learn prompt engineering, advanced techniques, practical applications, and productivity hacks. Save hours daily with AI assistance.
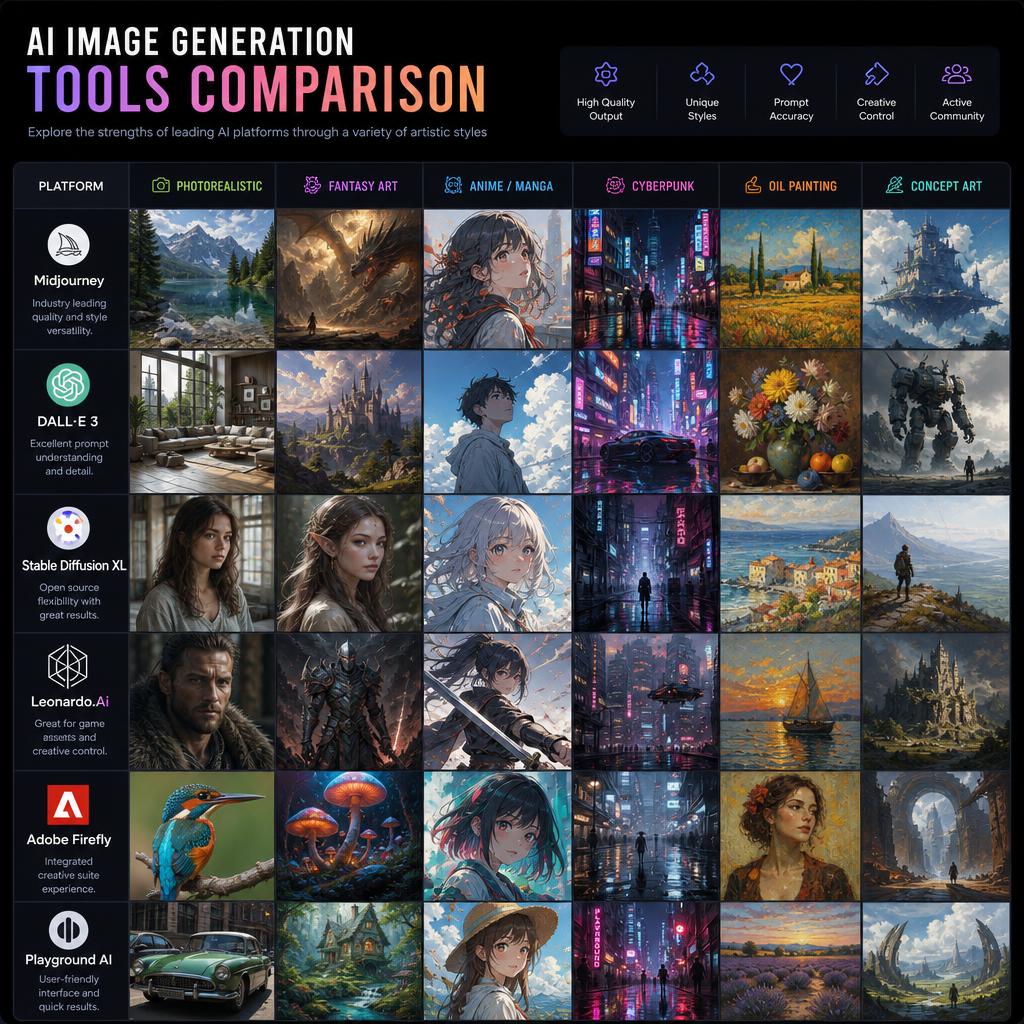
Best Midjourney Alternatives with Free API Access (2026)
Midjourney has no official API. These 6 alternatives offer free API access for AI image generation with no waitlist, comparable quality, and developer-friendly pricing.
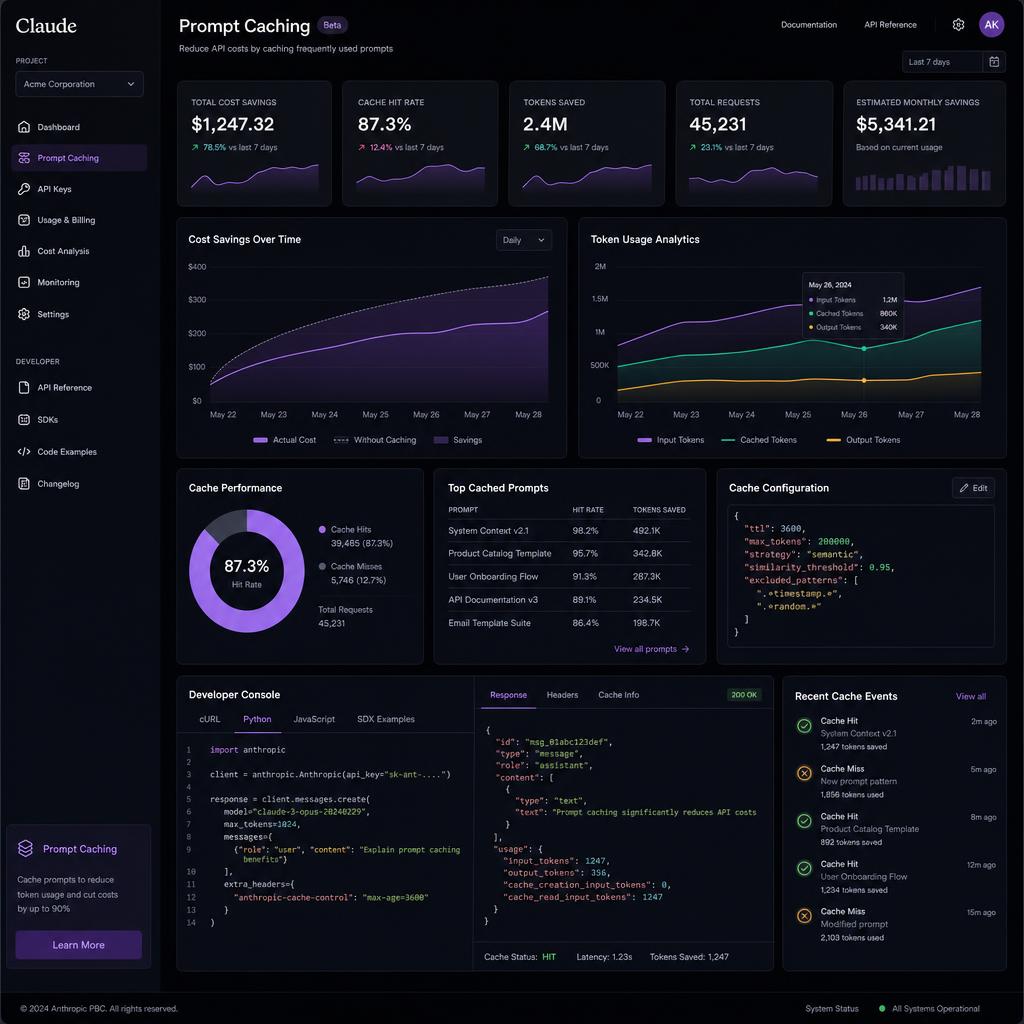
Cut Claude API Bills 40% with Prompt Caching — 2026 Guide
Anthropic's prompt caching context caching benchmark: Reduced token overhead on 50k+ token repetitive prompt tests. This step-by-step guide shows how to implement it and estimate your savings.
Best v0.dev Alternatives for Open-Source UI Generation (2026)
v0.dev by Vercel is powerful but expensive and closed-source. These 6 open-source and free alternatives generate production-ready UI from prompts in 2026.
30 Best ChatGPT Prompts to Boost Your Productivity in 2026
30 copy-paste ChatGPT prompts to boost productivity in 2026. Ready-to-use templates for work, business, learning, writing, and personal growth. Save hours daily.
AI Recruitment Tools - Automate Hiring & Screening 2026
Top AI recruitment tools in 2026. Compare features, pricing for resume screening, candidate matching, interview scheduling. Tested candidate matching & automated resume screening across 150 candidate profiles.
AI Legal Document Review - Best Tools for Lawyers 2026
Top AI legal document review tools in 2026. Compare features for contract analysis, due diligence, compliance. Tested contract redlining & clause risk analysis across 40-page commercial agreements.
Best AI Tools for Lawyers & Legal Professionals in 2026
Discover the top AI tools for lawyers in 2026—Spellbook, Harvey AI, Lexis+ AI & CoCounsel. Cut contract review time by 70% and boost firm profitability with AI.
Best AI Tools for Freelance Designers 2026 – Honest Review
Discover the best AI tools for freelance designers in 2026. Compare Figma AI, Adobe Firefly, Canva Magic Studio, Midjourney, and Krea with real pricing.
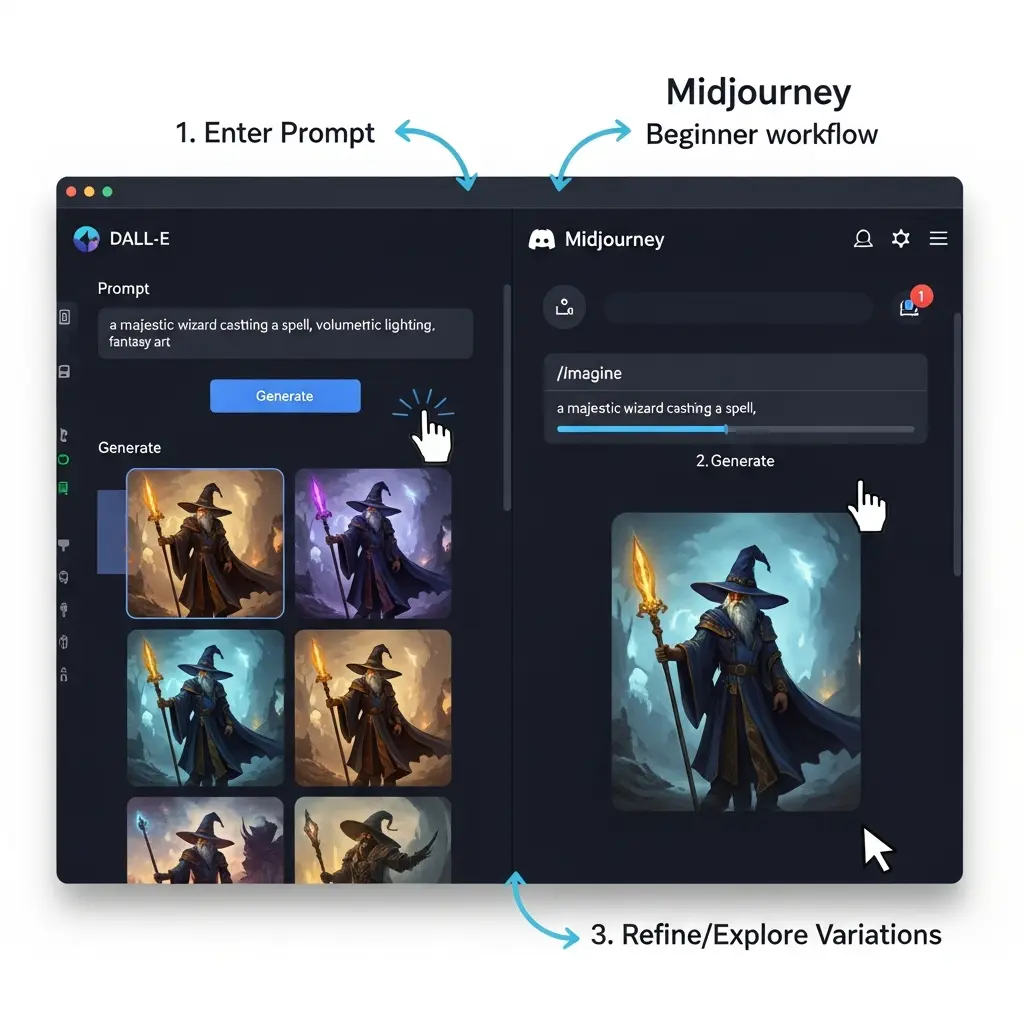
AI Image Generation Guide: Create Your First AI Art in 2026
Create your first AI image in 2026 with our step-by-step guide. Master Midjourney, DALL-E 3, and prompt engineering. Transform ideas into stunning visuals in minutes.
AI Plagiarism Detectors - Best Detection Tools 2026
Top AI plagiarism detection tools in 2026. Compare Turnitin, Grammarly, Copyscape features and accuracy. Detect AI-generated content and ensure originality with 99% accuracy.
Best AI Video Editing Tools 2026 – Descript, CapCut, Runway Compared
Compare the best AI video editing tools in 2026. Honest review of Descript, CapCut, Runway, Adobe Premiere AI, and InVideo with pricing and real use cases.
Top Free AI Tools for Students - Study Smarter in 2026
Best free AI tools for students in 2026. Boost grades with ChatGPT, Grammarly, Quizlet AI, and 17 more tools for writing, research, note-taking, and studying. Hands-on workflow testing and step-by-step setup guides.
Best AI Tools for Investing & Trading: Find Alpha in 2026
Discover the top AI investing tools in 2026—Trade Ideas, Magnifi, Kavout & Seeking Alpha. Hands-on testing of automated screener workflows, backtesting models, and risk analysis.
Best AI Tools for Music Production 2026 - Create Tracks Fast
AI music production tools for composition, mixing, mastering, and audio editing. Create professional tracks without expensive studio equipment.
Best AI Scheduling Tools 2026 – Motion, Reclaim, Clockwise Compared
Compare the best AI scheduling tools in 2026. Honest review of Motion, Reclaim AI, Clockwise, Morgen, and Cal.ai with real pricing and productivity results.
Best AI Travel Planning Tools & Apps for 2026 | Trip Planner
Discover the best AI travel tools for 2026—Mindtrip, Hopper & GuideGeek. Plan perfect trips in under 45 minutes and save up to 30% on total trip costs.
Best AI Tools for Video Editing 2026 - Create Videos Fast
AI video editing tools for content creators. Auto-captions, background removal, editing automation, and effects. Create videos 75% faster with zero experience.
Best AI Social Media Tools 2026 – Buffer, Hootsuite, Later Compared
Compare the best AI social media tools in 2026. Honest review of Buffer, Hootsuite, Later, Sprout Social, and Metricool with real pricing and features.
AI Trading Platform Guide 2026: Hidden Costs
AI trading platform reviews skip the real costs. See which tools hide bots behind paywalls, where free plans stop, and what to verify first.
AI for Interior Design: What Actually Works
AI for interior design can create stunning rooms and terrible plans. Learn which tools help with layouts, shopping, and client-ready visuals.
AI Tools for Law Firms: 2026 Pricing Guide
Compare ai tools for law firms with real pricing, acquisition risk, and confidentiality checks before your firm commits to the wrong platform.
AI Influencer Marketing Platform 2026 Guide
Choosing an ai influencer marketing platform 2026? See real pricing, hidden limits, and the questions that expose weak demos fast.
Customer Feedback Analysis AI: What Actually Works
Customer feedback analysis AI only works if your data collection does. See the setup costs, pricing gaps, and tool choices that matter.
Best AI Tools for HR & Recruitment 2026 - Hire Top Talent
AI recruitment tools for faster hiring, better candidate matches, and smarter HR. Resume screening, interview automation, and employee engagement.
Best AI Writing Tools for Bloggers 2026 – Honest Comparison
Discover the best AI writing tools for bloggers in 2026. Honest comparison of Jasper, Claude, ChatGPT, Writesonic, and SurferSEO — with real pricing and use cases.
6 designers 3 programmers 65 people game credits
6 designers, 3 programmers, 65 people in game credits: what the other 56 contributors likely did, and what that ratio actually tells you.
SpaceX acquires Cursor AI coding tool impact
SpaceX acquires Cursor AI coding tool June 2026 impact: what changes now, what to watch in the terms, and when switching tools actually makes sense.
Best AI Survey Tools 2026 - Get Better Customer Insights
Discover top AI survey and feedback tools in 2026. Automate analysis, detect sentiment, predict trends, and get actionable insights 10x faster. Compare features and pricing.
Best AI Tools for E-commerce 2026 - Increase Sales & Revenue
AI tools for e-commerce businesses. Product recommendations, personalization, inventory management, and customer service. Increase average order value 30-40%.
Best AI Presentation Tools 2026 – Create Slides Instantly
Compare the best AI presentation tools of 2026 including Gamma, Beautiful.ai, Plus AI, Canva, and Pitch. Honest pricing, features, and which one is right for you.
Claude Fable 5 vs MAI-Thinking-1 June 2026
Claude Fable 5 vs MAI-Thinking-1 benchmark comparison June 2026: published scores, missing Microsoft data, pricing, and what buyers can decide now.
Google Cloud AI Automates Council Planning: Worth It?
Google Cloud generative AI automates council planning operations, but naive deployments fail legal audits. Here is how to use it well in 2026.
AI Tools for Graphic Design: Midjourney vs Firefly
Stop chasing prompt hacks. The real battle between top AI tools for graphic design isn't about style—it's about vector control and asset consistency.
AI for Financial Reporting: True Costs & Reality Check
Think AI for financial reporting is a cheap time-saver? Read our pricing reality check on the hidden formatting and audit trail costs of automated finance.
AI Tools for Business Development: The Real Cost
Stop wasting budget on hidden integration taxes. Discover how AI tools for business development actually perform in the real world without breaking.
AI Tool for Image Generation: Ultimate Guide for 2026
AI Tool for Image Generation: Ultimate Guide for 2026
AI Tools for Business Development: The Real Cost
Before you buy AI tools for business development, learn how dirty CRM data and hidden credit pricing structures can quietly drain your budget in 2026.
Best AI Tools for Business Development 2026: How to Choose
Avoid credit-blowouts and bad CRM data. Learn how to choose the best AI tools for business development in 2026 before you waste your budget.
Claude vs ChatGPT for Content Marketing 2026: How to Choose
Avoid rate limits and brand voice drift. Here is how to choose Claude vs ChatGPT for content marketing 2026 based on actual production bottleneck realities.
Gemini 2.5 Pro vs Claude Opus 4 for Coding 2026 Guide
Don't get trapped by Claude's 60s latency or Gemini's hidden setting. Read our Gemini 2.5 Pro vs Claude Opus 4 for coding 2026 guide.
Latest AI New Tools: Complete Comparison of Real Costs
The latest ai new tools promise 4x code output but trigger a 54% spike in bugs. Here is a complete comparison of how to deploy them without going broke.
AI Tool for Presentation: The Honest 2026 Review
Looking for an AI tool for presentation? Here is the honest truth about export bugs, brand font lock-in, and how to avoid generic slide syndrome.
Gemini 3 vs GPT-5.5 vs Claude Opus 4.8 June 2026
Confused by the June 2026 LLM wars? We break down Gemini 3 vs GPT-5.5 vs Claude Opus 4.8 with raw benchmarks, pricing, and speed specs for beginners.
AI Tools for Graphic Design: The Real Workflow That Works
Stop wasting credits on prompt paralysis. Here is why the hybrid pipeline is the only way to use AI tools for graphic design while keeping brand consistency.
What Nobody Tells You About Claude Opus 4.8 vs GPT-5.5 in Re
What Nobody Tells You About Claude Opus 4.8 vs GPT-5.5 in Re
Best AI Tools for Accountants 2026 - Automate Bookkeeping
AI accounting tools for bookkeeping, tax prep, financial planning, and audit. Reduce manual work 60%, improve accuracy 95%+. Perfect for CPAs.
Best AI Research Tools 2026 – Perplexity, Elicit, Consensus Compared
Discover the best AI research tools in 2026. Compare Perplexity AI, Elicit, Consensus, ChatGPT Deep Research, and more with real pricing and honest reviews.
Best AI Tools for Real Estate 2026 - Sell Properties Fast
AI tools for real estate professionals. Property valuation, listing optimization, lead generation, and virtual tours. Close deals 30% faster with less effort.
Best AI Tools for Teachers 2026 – MagicSchool, Khanmigo, Brisk Compared
Find the best AI tools for teachers in 2026. Compare MagicSchool AI, Khanmigo, Brisk Teaching, Diffit, and SchoolAI with real pricing and classroom results.
Start a Faceless YouTube Channel with AI Tools (2026 Guide)
Learn how to start a profitable faceless YouTube channel in 2026 using AI tools. Full automation guide covering niche selection, scripting, voiceover, editing, and monetization.
Best AI Tools for Customer Service 2026 - Automate Support
AI customer service tools for faster response times, better resolution, and happier customers. Reduce support costs 40-60% with these 8 essential tools.
Best AI Tool for Video Creation: What Actually Matters
Choosing the best ai tool for video creation? Most tools break down on length, audio, or pricing. Here’s how to pick without wasting hours.
Best AI Tool for Video Creation: What Holds Up
Looking for the best ai tool for video creation? See which tools hold up past short demo clips, where pricing breaks down, and what fails first.
AI Tools for Data Analysis 2026 - Extract Insights Fast
AI data analysis tools extract insights 10x faster. ChatGPT Code Interpreter, Tableau AI, and more. Turn raw data into action in minutes.
Best AI Photo Editing Apps 2026 – Top Tools Compared
Find the best AI photo editing apps in 2026. Compare Adobe Firefly, Luminar Neo, Canva AI, Lightroom, and Photoroom with real pricing and use cases.
AI Based Web Development: Tool Comparison 2026
AI based web development tools save time, but many fail under real production constraints. Compare pricing, tradeoffs, and where each tool fits.
AI Trading Platform Pros and Cons 2026
AI trading platform costs vary fast: Holly AI is $254/month, 3Commas needs $29/month for live bots, and mobile features often lag desktop.
AI Shift From Chatbots to Agents: Cost Guide
AI development has shifted from basic chatbots toward autonomous AI agents and edge computing. See why pilots stall and what production really costs.

Best AI Tools for Marketing Teams 2026 - Automate & Scale
AI tools for marketing teams including content, email, social, SEO, analytics, and personalization. 50% faster campaigns with 30% better ROI.
Figma Design Agent Launch 2026 – AI Co-Designer in Figma
Figma launched its Design Agent on May 20, 2026 — an AI that works alongside designers in real-time. Here's what it does, how it works, and what designers think.
AI Content Generator Tools and LLM Models Guide
Compare ai content generator tools and llm models by cost per usable draft, context limits, and workflow fit—not token price alone.
AI Video Generator Costs and Limits in 2026
Thinking about an ai video generator? Compare clip costs, free-tier limits, and the mistakes that waste credits before you pay.
6 Designers 3 Programmers 65 People Game Credits
What the "6 designers, 3 programmers, 65 people" game credits story reveals about missing standards, unreadable credits, and risky public promises.
AI Agent Latest News May 2026: What Matters
AI agent latest news May 2026, minus the hype: prices, deployment risks, benchmark gaps, and the compliance deadline teams are missing.
"60 Staff-Hours" Facilities Voice AI Claim Examined
The "60 staff-hours" facilities management voice AI claim sounds impressive. Here’s what to verify on pricing, call spikes, and CMMS fit before buying.
60 Staff-Hours FM Voice AI: How to Choose
The “60 staff-hours” facilities management voice AI claim is unverified. Use this framework to compare pricing, integrations, and real ROI.
60 Staff-Hours Facilities Voice AI Guide
60 staff-hours facilities management voice AI claims rarely cite proof. See what FM teams can measure, what breaks ROI, and which tools fit.
AI content authentication standards Google SynthID
AI content authentication standards Google SynthID now affect what Chrome shows on AI images. See what changed in May 2026 and how creators should respond.
Top AI Animation Software 2026: Honest Tool Ranking
Top AI animation software 2026, tested on real projects. See pricing, licensing limits, credit burn, and which tools hold up under deadline pressure.
Gemini 2.5 Pro vs GPT-5.5 vs Claude Opus 4.7
Gemini 2.5 Pro vs GPT-5.5 vs Claude Opus 4.7 May 2026: pricing, context windows, and the failure modes that matter before you pick one.
Gemini 3.5 Flash vs GPT-5.5 vs Claude Opus 4.7
Gemini 3.5 Flash vs GPT-5.5 vs Claude Opus 4.7 May 2026: compare pricing, context, writing quality, and API fit before you commit.
Best AI Photo Restoration Tools 2026 Guide
Best AI photo restoration tools 2026: compare prices, strengths, and risks so you can restore old photos without waxy faces or bad subscriptions.
AI Agent Product Launch May 2026: What to Check
AI agent product launch May 2026: avoid the trust, memory, pricing, and governance mistakes that sink pilots after the demo phase.
AI Agent Product Launch May 2026: Cost Breakdown
AI agent product launch May 2026 analysis: real pricing, Microsoft licensing risks, and the hidden costs buyers miss before rollout.
AI agent product launch May 2026: what’s real
AI agent product launch may 2026: what’s actually shipping, what’s gated, and where pricing and governance will trip up buyers.
Hidden Costs of AI Agent Launches in 2026 — Full TCO Breakdown
85% of organizations misestimate AI agent costs by over 10%. Here is what actually drives TCO beyond the vendor quote — infrastructure, compliance, ops, and data pipelines.
Why AI Agent Launches Fail at Month 3 — 2026 Data and Root Causes
76% of AI agent implementations fail within 90 days. Here is the breakdown of why month 3 collapses happen and what the 12% that survive do differently.
og:title
AI-driven virtual events can improve meetings, segmentation, and support—but only if you track the right outcomes. Here's what actually works in 2026.
AI-Driven Virtual Events: What Actually Works
Planning ai-driven virtual events? Learn which platforms justify the spend, where teams waste budget, and what to fix before buying AI features.
Best AI Tools for Product Descriptions and Meta Titles in 2026
The practical guide to using AI for e-commerce product descriptions and SEO meta titles in 2026. Real pricing, honest tradeoffs, and the workflow that actually works.
Anthropic Surpasses OpenAI in Enterprise Adoption -- May 2026
Anthropic is outpacing OpenAI in new enterprise AI contracts in 2026. We break down why it's happening, what the data shows, and whether it's durable.
Anthropic on SpaceX Colossus: Claude Rate Limits Double in May 2026
Anthropic is now running Claude on SpaceX's Colossus supercomputer. Here's the business logic behind the deal, what it means for idle GPU capacity, and why your Claude rate limits just doubled.
Canva AI Tutorial: Master AI Design Features in 2026
Complete Canva AI tutorial for 2026. Master Magic Write, Magic Design, Background Remover, and AI image generation. Create professional designs in minutes, not hours.
Claude vs GPT-5.5 Benchmarks — May 2026
Claude vs GPT-5.5 intelligence benchmark comparison May 2026: see which model wins for coding, PDFs, OCR, and $200/month workflows.
GPT-5 vs Claude Opus 4.7 Benchmarks May 2026
GPT-5 vs Claude Opus 4.7 intelligence benchmark comparison May 2026: what scores miss, where each model wins, and which is cheaper to run.
Anthropic SpaceX Colossus Deal: Claude Rate Limits Doubled May 2026
Anthropic is routing Claude through SpaceX's Colossus cluster. Here's why it happened, what changed for API users, and what it means for power users.
"Total 65" game credits: designers, programmers
"Total 65" game credits designers programmers: what the viral mistake teaches studios about AI-assisted credits tracking and safer workflows.
Microsoft Agent 365 E7 Frontier Suite May 2026: What IT Teams Need to Know
Microsoft Agent 365 and E7 Frontier Suite launched May 2026. Here's what the $99 tier actually changes for enterprise IT teams and end users.
AI Game Development Tools 2026 Guide
Discover how to utilize ai game development tools 2026 for creating innovative games. Step-by-step guide on asset creation, coding, and deployment.
Choosing AI Tools for Video Creation 2026
Discover how to select the ideal AI tools for video creation in 2026. Compare features, pricing, and use cases with our detailed guide.
AI Stock Trading Tools 2026: Trade Ideas, Tickeron, Composer Reviewed
AI stock trading tools in 2026 reviewed. Trade Ideas, Tickeron, Composer, Danelfin — what they cost, what they actually do, and the risks most guides skip.
Best AI Tools for Small Business 2026
Find the best AI tools for small business 2026. Compare top picks for automation, writing, support, and admin in one practical guide.
Best AI Writing Tools 2026: Top Picks
Discover the best AI writing tools 2026 offers. Compare features, pricing, and top use cases for Jasper, Copy.ai, Sudowrite, Grammarly, and more.
Anthropic Surpasses OpenAI in Business Adoption 2026: What the Data Shows
Anthropic is outpacing OpenAI in enterprise AI adoption in 2026. Here's why Claude is winning business deals — and why the cost hit users faster than expected.
Best AI Email Marketing Tools 2026: Tested and Ranked
The best AI email marketing tools in 2026 reviewed. Klaviyo, Mailchimp, ActiveCampaign, Jasper — what actually improves open rates and revenue.
LLM Model Comparison 2026: GPT-4o vs Claude vs Gemini vs Llama Trade-Offs
LLM comparison for 2026 that focuses on real trade-offs: speed, cost, context, quality, and reliability across GPT-4o, Claude 3.5, Gemini 2.0, and Llama 3.3.
Latest LLM Models 2026: What Breaks First When You Trust the Benchmark Hype
The latest LLMs in 2026 break in specific, predictable ways when users trust benchmark hype. Here's what actually fails first across GPT, Claude, Gemini, and Llama.
Running a 70B LLM on 36GB RAM: LLM Compression Techniques in 2026
Running Llama 3.3 70B on 36GB RAM with modern quantization. Here's what compression actually looks like in 2026, and what it costs you in quality.
AI E-Commerce Tools 2026: Agentic Commerce Guide for Beginners
Agentic commerce explained for e-commerce beginners in 2026. What AI tools actually help Shopify stores sell more, what costs what, and where to start.
Best AI Tools for Unreal Engine 5 Development 2026: Tested and Ranked
The best AI tools for Unreal Engine 5 development in 2026. Copilot, Cursor, Cascadeur, AI audio — what actually saves time and what creates rework.
Building a Playable Game with AI Tools in 30 Days: What Actually Shipped in 2026
30 days, one solo developer, AI tools for code, art, and audio. Here's the exact workflow — including what broke and what finally shipped.
AI for Financial Reports 2026: ChatGPT vs Claude vs Gemini vs Finance Platforms
Using AI for financial reports in 2026. Comparing ChatGPT, Claude, Gemini, Copilot for Finance, Planful, and Mosaic on real financial analysis tasks.
AI Tools for Game Developers 2026: Why Generated Code Breaks and What Works
AI code generation breaks in game dev for specific reasons. Here's why, what actually works in Unity and Unreal, and the workflow patterns that ship games.
Llama 3 vs Mistral vs Claude: Open Source LLM Comparison 2026
Three weeks testing Llama 3.3, Mistral Large 2, and Claude 3.5 on real tasks. Here's exactly where each model breaks down first.
AI for Architecture 2026: Where Firms Are Actually Saving Time
AI is finally saving real time in architecture firms in 2026. Autodesk Forma, TestFit, Hypar, and BIM AI tools — where the hours actually go.
AI Supply Chain Software 2026: What Vendors Don't Tell You Before You Sign
The real implementation timeline, hidden costs, and change management requirements of AI supply chain software in 2026 — what you won't hear in the sales cycle.
AI Architecture Software Tested 2026: 9 Tools on Real AEC Projects
9 AI architecture tools tested on real AEC projects in 2026. Find out which saved hours, which caused rework, and which are worth the subscription.
AI Supply Chain Software Tested 2026: 6 Tools on Real Operations Data
6 AI supply chain tools tested with real ops data. One tool actually helped planners work faster. Here's the breakdown for 2026.
AI Animation Tools 2026 Tested: Cascadeur, Runway, DeepMotion Reviewed
I spent $200 testing 6 AI animation tools in 2026. Cascadeur, Runway Gen-3, DeepMotion, Animate Anyone — what actually works for game dev, video, and motion.
AI in Architecture 2026: How AI Renders Sell Bad Designs and What to Do About It
AI visualization tools make every architectural concept look compelling. Here's the specific problem this creates and how firms are managing client expectations.
AI Tax Software 2026 Tested: TurboTax, H&R Block, FlyFin, Keeper Reviewed
I tested TurboTax AI, H&R Block AI Tax Assist, FlyFin, and Keeper. Most taxpayers need far less than the marketing suggests. Here's the honest breakdown.
Automate Product Descriptions with AI 2026: What Breaks at Scale
Automated 2,000 product descriptions and meta titles with AI in 2026. Here's what broke, what worked, and how to fix the output quality issues.
AI Tax Software: Best Tax Prep Tools 2026
Discover the best AI tax preparation software for 2026. Compare features, pricing, and accuracy for individuals and businesses. Maximize deductions with AI.
AI Sales CRM: Best Tools for Sales Teams 2026
Discover the best AI sales CRM tools for 2026. Compare features, pricing, and automation capabilities for lead management, pipeline tracking, and revenue growth.
AI Real Estate Tools 2026: Complete Platform Guide
Discover the best AI real estate tools for 2026. Compare property valuation, lead generation, virtual tours, and market analysis platforms for agents and investors.
20 Best AI Tools for Content Creators - Ultimate List 2026
Discover 20 hands-on tested AI tools for creators in 2026. Compare features, pricing, and use cases for writing, design, video, SEO, and social media. Hands-on workflow testing and step-by-step setup guides.
AI Voice Cloning: Top Tools & Platforms 2026
Discover the best AI voice cloning tools for 2026. Compare features, pricing, and quality for realistic voice synthesis, dubbing, and audio content creation.
Best AI Animation Tools 2026: Complete Guide
Discover the best AI animation software for 2026. Compare features, pricing, and capabilities for 2D/3D animation, motion capture, and automated animation creation.
Gemini AI vs ChatGPT: Complete Comparison 2026
Gemini vs ChatGPT 2026: Complete comparison of features, pricing, accuracy, and use cases. Discover which AI chatbot wins for coding, research, creativity, and business.
AI Content Moderation Tools: Top Platforms 2026
Discover the best AI content moderation tools for 2026. Compare features, pricing, and accuracy for automated text, image, and video moderation at scale.
Best AI Graphic Design Tools 2026 | Design 10x Faster
Discover top AI graphic design tools in 2026. Compare features, pricing, and capabilities of Canva AI, Adobe Firefly, Midjourney, and more. Create stunning designs effortlessly.
Best AI Video Editing Software 2026 | Edit 10x Faster
Master AI video editing with top tools in 2026. Compare Descript, Runway ML, Adobe Premiere Pro AI, and more. Cut editing time by 60% with smart automation.
AI Music Creation Tools 2026 | Compose Like a Pro
Discover top AI music creation tools in 2026. Learn about AIVA, Soundraw, Mubert, and more. Create royalty-free music, beats, and soundtracks instantly with AI.
Top AI Tools to Save 2+ Hours Every Day - Ultimate Guide 2026
Save 2+ hours daily with these 29 AI tools for 2026. Complete guide to AI automation for email, writing, design, video, research, and productivity. Real time-saving metrics included.
Best AI Coding Assistants 2026 | Code 3x Faster
Master AI coding with GitHub Copilot, Cursor, Tabnine, and more. Compare features, pricing, and capabilities. Debug faster, learn quicker, boost productivity by 55%.
AI Interior Design Tools - Redesign Your Space 2026
Top AI interior design tools in 2026. Compare Planner 5D, RoomGPT, Decoratly features. Visualize room redesigns in seconds with AI. Free and paid design assistants compared.

Best AI Tools for Small Business 2026 - Automate & Scale
Top AI tools for small business owners. Automate operations, customer service, marketing, and accounting. Save $50K+ annually with these 12 essential tools.
AI Data Analytics Tools 2026 | Insights in Minutes
Discover top AI data analytics tools in 2026. Compare Tableau AI, Power BI, ThoughtSpot, and more. Analyze data 10x faster with automated insights and visualizations.
Top AI Tools for Freelancers 2026 - Boost Income & Productivity
Discover the 15 best AI tools for freelancers in 2026. Automate tasks, win more clients, and increase rates with tools for proposal writing, project management, and client communication.
AI Podcast Editing Tools - Automate Audio Production 2026
Top AI podcast editing software in 2026. Compare Descript, Adobe Podcast, Auphonic features. Reduce editing time by 75% with AI audio enhancement, transcription, editing.
Best AI Tools for Cybersecurity 2026 - Threat Detection
AI cybersecurity tools for threat detection, vulnerability management, and incident response. Real-time protection against evolving threats.
Best AI Translation Tools 2026 | Translate Instantly
Discover top AI translation tools in 2026. Compare DeepL, Google Translate, ChatGPT, and more. Get accurate translations in 100+ languages instantly with AI.
AI Medical Diagnosis Tools - Healthcare AI Assistants 2026
Explore AI medical diagnosis assistants in 2026. Compare tools helping doctors with disease detection, imaging analysis, clinical decisions. Improve diagnostic accuracy by 35%.
AI Tools for Healthcare Professionals 2026 - Clinical Support
AI tools for medical professionals including diagnosis support, documentation automation, patient engagement, and clinical research. HIPAA compliant.
Best AI Tools for Project Management 2026 - Delivery On Time
AI project management tools for better planning, resource allocation, and on-time delivery. Automation, forecasting, and risk prediction.
Best AI Game Development Tools 2026 - Create Games Faster
Discover top AI game development tools in 2026. Automate coding, generate art, create music, and build games 10x faster. Compare features, pricing, and use cases.
Best AI Voice Assistants 2026 | Smart Home Guide
Compare top AI voice assistants in 2026: Alexa, Google Assistant, Siri, and more. Control smart homes, automate tasks, and boost productivity with voice commands.
Best AI Architecture Software 2026 - Design Buildings Faster
Discover top AI architecture design tools in 2026. Automate floor plans, generate 3D models, optimize designs, and reduce project time by 40%. Compare features and pricing.
Best AI Tools for Teachers 2026 - Enhance Student Learning
AI tools for educators and teachers. Automate grading, personalize learning, create lesson plans, and improve student outcomes. Hands-on workflow testing and step-by-step setup guides.
AI Email Writing Tools 2026 | Write Faster
Master AI email writing with top tools in 2026. Compare Grammarly, Jasper, Copy.ai, and more. Write professional emails in seconds with AI assistance.
Best AI Fashion Design Tools 2026 - Design Clothing Faster
Discover top AI fashion design tools in 2026. Generate designs, create patterns, visualize fabrics, and launch collections 10x faster. Compare features and pricing.
AI Language Learning Apps - Best Tools to Learn Fast 2026
Top AI language learning apps in 2026. Compare Duolingo, Babbel, Rosetta Stone with AI features. Learn languages 3x faster with personalized AI tutors and conversation practice.
AI Logo Design Generators - Create Professional Logos 2026
Top AI logo generators in 2026. Compare Looka, LogoAI, Brandmark features and pricing. Create professional logos in minutes without design skills. Free and paid options.
AI Social Media Management 2026 | Automate Posts
Discover top AI social media tools in 2026. Compare Buffer, Hootsuite AI, Lately, and more. Automate scheduling, content creation, and analytics effortlessly.
Top AI Tools for Fitness & Personal Development 2026
Achieve fitness goals faster with AI tools. Explore top workout, nutrition, and recovery AI like MacroFactor, WHOOP, and Alpha Progression for 2026.
AI Meeting Transcription - Best Tools & Software 2026
Compare top AI meeting transcription tools. Otter.ai vs Fireflies vs Fathom features, accuracy, pricing. Automatically transcribe and summarize meetings in real-time.
AI Resume Builders 2026 | Professional Resumes Fast
Discover top AI resume builders in 2026. Compare Rezi, Resume Worded, Kickresume, and more. Create ATS-optimized resumes that get interviews with AI assistance.
Best AI Stock Trading Platforms 2026 - Invest Smarter
Discover top AI stock trading platforms in 2026. Automate trades, analyze markets, predict trends, and maximize returns. Compare features, pricing, and performance.
Best AI Email Marketing Tools 2026 - 10x Your Campaigns
Discover top AI email marketing tools in 2026. Automate campaigns, personalize content, optimize send times, and increase conversions by 40%. Compare features and pricing.
Best AI Grammar Checkers - Writing Tools Comparison 2026
Compare the best AI grammar checkers in 2026. Grammarly vs ProWritingAid vs QuillBot features, pricing, accuracy. Write flawless content faster with AI assistance.
Best AI Tools for Language Learning: Reach Fluency in 6 Months
Discover the top AI language learning apps in 2026—Speak, Praktika, Langua & ELSA Speak. Reach B2 conversational fluency in 6 months with AI-powered tutors.
AI Customer Service Chatbots: Best Tools 2026
Discover the best AI customer service chatbots in 2026. Compare features, pricing, and integration options. Improve response times by 90% and automate Tier-1 routing with benchmarked 94% intent classification accuracy.
AI Financial Planning Tools - Smart Money Management 2026
Discover the best AI financial planning tools in 2026. Compare features, pricing, and benefits. Automate budgeting, investing, and achieve financial goals faster.
Best AI Tools for Fashion Retail 2026 - Trend Prediction
AI fashion tools for trend forecasting, inventory optimization, and personalized styling. Reduce returns 30%, increase sales 40% with AI.
Best AI Game Art Generators 2026 - Create Game Assets Fast
Discover the top AI game art generators in 2026. Create characters, environments, textures, and UI elements in minutes. Save 60-80% on asset creation time.
AI Fitness Apps 2026 | Smart Personal Training Tools
Discover top AI fitness coaching apps for personalized workouts, nutrition tracking, and health monitoring. Get expert training powered by artificial intelligence.
AI SEO Tools: Best Optimization Software 2026
Discover the best AI SEO optimization tools in 2026. Compare Surfer SEO, Clearscope, Frase, and more. Rank higher in Google with AI-powered content optimization and keyword research.
Best AI Tools for Web Developers: Ship Faster in 2026
Discover the top AI coding tools for web developers in 2026—Cursor, v0 by Vercel, Claude Code & GitHub Copilot. Ship features 3–5x faster with AI-native IDEs.

ChatGPT for Beginners 2026 | AI Conversation Guide
Learn ChatGPT from scratch! Master AI conversations, prompts, and productivity hacks. Complete beginner guide with examples and tips for 2026.
Top AI Mental Health Apps 2026 - Therapy & Support Tools
Discover the best AI mental health apps in 2026. Compare AI therapy chatbots, mood trackers, meditation apps, and crisis support. Affordable mental wellness tools.
Best AI Tools for Non-Profits: Fundraise Smarter in 2026
Discover the top AI tools for non-profits in 2026—Dataro, Fundraise Up, Grantable & Givebutter. Cut admin work by 40% and grow your donor base with AI.
AI Presentation Makers: Best Tools 2026
Discover the best AI presentation makers in 2026. Create professional slides in minutes with Gamma, Beautiful.ai, Tome, and more. Save 5+ hours per presentation.

Best AI Tools for Students 2026 | Study Smarter with AI
Discover the top AI tools that students should use in 2026 to boost productivity, organize notes, write essays, revise effectively, and master difficult topics.
Claude AI Assistant Guide 2026 | Advanced AI Tool Tutorial
Master Claude AI with this complete 2026 guide. Learn advanced features, use cases, prompting techniques, and how Claude compares to ChatGPT for professionals.
ChatGPT Complete Guide: From Beginner to Advanced User
Discover how to use ChatGPT for content creation, productivity, and learning. Step-by-step beginner to advanced tips for AI tools enthusiasts.

Discover the Latest Technology Trends 2026 – AI, Robotics, and More
Explore the latest technology trends of 2026, including AI, robotics, blockchain, and quantum computing. Learn how these innovations are shaping the future.
AI Agriculture Tools 2026 - Smart Farming & Crop Monitoring
Discover the best AI agriculture monitoring platforms in 2026. Optimize crop yields, predict issues, and reduce costs with precision farming technology.
AI Photo Editing: Best Tools & Software 2026
Discover the best AI photo editing tools in 2026. From Photoshop AI to Luminar Neo, compare features for background removal, enhancement, and professional editing.
Perplexity AI Search Guide 2026 | AI-Powered Research Tool
Master Perplexity AI with this complete 2026 guide. Learn real-time web search, sources, Pro features, and how to research better using AI reasoning.
Top AI Recipe Generators 2026 - Create Custom Recipes Instantly
Discover the best AI recipe generators in 2026. Create personalized recipes from ingredients, dietary needs, and preferences. Save time meal planning.
AI Scheduling Assistants: Best Tools 2026
Discover the best AI scheduling assistants in 2026. Automate meeting bookings with Calendly, Motion, Reclaim, and more. Save 5-10 hours weekly on calendar management.
Google Gemini AI Guide 2026 | ChatGPT Alternative
Master Google Gemini AI! Learn how to use Gemini for research, coding, creative writing, and productivity. Complete beginner's guide with tips.
AI Shopping Assistants 2026 - Smart Product Recommendations
Discover the best AI personal shopping assistants in 2026. Get personalized recommendations, price alerts, and smart deals. Save time and money shopping.
AI Research Assistants: Best Tools 2026
Discover the best AI research assistants in 2026. Find accurate information faster with Perplexity AI, Elicit, Consensus, and more. Cut research time by 60-80%.
Beautiful.ai Guide 2026 | AI Presentation Design Made Easy
Master Beautiful.ai for stunning presentations. Learn AI slide design, templates, automation, and create professional slides 10x faster. Complete 2026 guide.
AI Contract Generators 2026 - Create Legal Docs Fast
Discover the best AI legal contract generators in 2026. Create NDAs, contracts, and agreements instantly. Save thousands on legal fees with AI-powered tools.
AI Product Description Generators: Best Tools 2026
Discover the best AI product description generators in 2026. Create compelling e-commerce copy with Jasper, Copy.ai, Writesonic, and more. Hands-on workflow testing and step-by-step setup guides.
Hugging Face Guide 2026 | AI Models and Datasets Hub
Master Hugging Face for AI development. Learn model selection, fine-tuning, deployment, and building with state-of-the-art AI models. Complete 2026 guide.
AI Marketing Analytics: Top Tools to Track ROI in 2026
Discover the best AI marketing analytics tools in 2026. Track campaign performance, predict trends, and optimize ROI with AI-powered insights. Hands-on workflow testing and step-by-step setup guides.
AI Photo Restoration: Restore Old Photos Instantly in 2026
Discover the best AI photo restoration tools in 2026. Fix damaged photos, colorize black & white images, and enhance old pictures automatically. Save hours vs manual editing.
AI 3D Modeling: Top Tools to Create 3D Models Fast in 2026
Discover the best AI 3D modeling software in 2026. Create professional 3D models from text, images, or sketches in minutes. Perfect for game dev, design, and visualization.
AI Music Recommendations: Top Engines & How They Work 2026
Discover how AI music recommendation engines like Spotify, Apple Music, and YouTube work. Learn the algorithms behind personalized playlists and discover new music perfectly.
AI HR Onboarding: Top Platforms to Automate New Hire in 2026
Discover the best AI HR onboarding platforms in 2026. Automate paperwork, personalize training, and improve new hire retention 40%. Save 15+ hours per employee.
AI Resume Screening: Top Tools to Filter Candidates in 2026
Discover the best AI resume screening tools in 2026. Automatically filter, rank, and match candidates in seconds. Reduce time-to-hire by 50% and improve quality-of-hire.
AI Appointment Booking: Top Tools to Automate Scheduling 2026
Discover the best AI appointment booking systems in 2026. Automate scheduling, automate multi-channel reminders and eliminate back-and-forth emails. Hands-on workflow testing and step-by-step setup guides.
Best AI Supply Chain Management Tools & Platforms 2026
Explore the top AI supply chain management platforms for 2026—Kinaxis, Blue Yonder, project44 & SAP IBP. Cut lead times by 27% with AI-driven logistics.
Best AI Customer Feedback Analysis Tools & Platforms 2026
Compare the top AI customer feedback analysis tools for 2026—Viable, Thematic, Chattermill & Qualtrics XM. Boost CSAT by 35% with smart VoC AI platforms.
Top AI Lead Generation Tools: Best Platforms in 2026
Discover top AI lead generation platforms in 2026. Clay, Apollo.io, Cognism, and 6sense help B2B teams find verified leads and triple reply rates.
Best AI Influencer Marketing Tools & Software 2026
Top AI influencer marketing platforms in 2026. Detect fake followers, predict ROI, and automate outreach with Modash, Upfluence, and HypeAuditor.
The Ultimate Guide to AI Virtual Event Platforms 2026
Compare the top AI virtual event platforms in 2026. Goldcast, Bizzabo, and HeyGen help B2B teams boost engagement and drive qualified sales pipeline.
How to Start a Profitable Faceless YouTube Channel in 2026: The Ultimate AI Automation Guide
Stop trading time for money. Learn the exact blueprint to build a 6-figure faceless YouTube channel using AI. Master vidIQ, ElevenLabs, Replit, and high-end hardware to automate your empire. No camera required.
No matching articles found
We couldn't find any articles matching your search query. Try checking for typos or searching for a broader term.